


- OverviewOverview
- Testing on real, public documentsTesting on real, public documents
- Measuring on public benchmarksMeasuring on public benchmarks
- How Lens worksHow Lens works
- What's nextWhat's next
Overview
Suppose an AI model reads an invoice with a line for 10 units at $5. The line should total $50, but the model records $5. Nothing looks broken. Every number is on the page and the output is neatly formatted. So the mistake moves on to the next step, and no one notices until a payment record is wrong.
Invoices are one kind of document. Contracts, bank statements, policies and filings are others. Together they hold most of a company's agreements and decisions, and a lot of operational work starts with reading them.
Pointer runs this operational work without a person checking each step. If it reads one field wrong, every step after it uses the wrong value, and the work fails.
We built Lens, our document engine, because this work depends on every value being right. A bank statement can hold hundreds of values, and one wrong value breaks the whole reconciliation. Lens runs in production today. To see how it holds up beyond our own documents, we tested it on two public benchmarks.
On ParseBench, which tests turning pages into text and tables, Lens ranks second of 145 systems, behind only the parser from the benchmark's own publisher. On ExtractBench Pro, which has 100 deliberately hard documents, Lens gets 58 of those documents 100% right with zero mistakes, the top score on the leaderboard, at a fraction of the cost of the one system that matches it.
Starting from existing tools
The first generation of document tools used optical character recognition (OCR) and templates. OCR turns a scanned image into text. A template tells the software where each field sits on the page. This works until the layout changes, a scan comes in skewed, or someone writes on the page.
Intelligent document processing (IDP) replaced templates with models trained on labeled examples of each document type. It handled more variation. But every new document type needed new training data, and new layouts still tripped it up.
Most finance and operations teams process invoices and orders with one of these two approaches. An AP leader told us their procure-to-pay tool's OCR fails on about 40% of invoices. Their team keys those in by hand.
Here is what that looks like on three real invoices, read once by OCR with a fixed template and once by Lens. The template is a free OCR engine (Tesseract) reading boxes drawn by hand for one layout. Orange cells are wrong or blank.
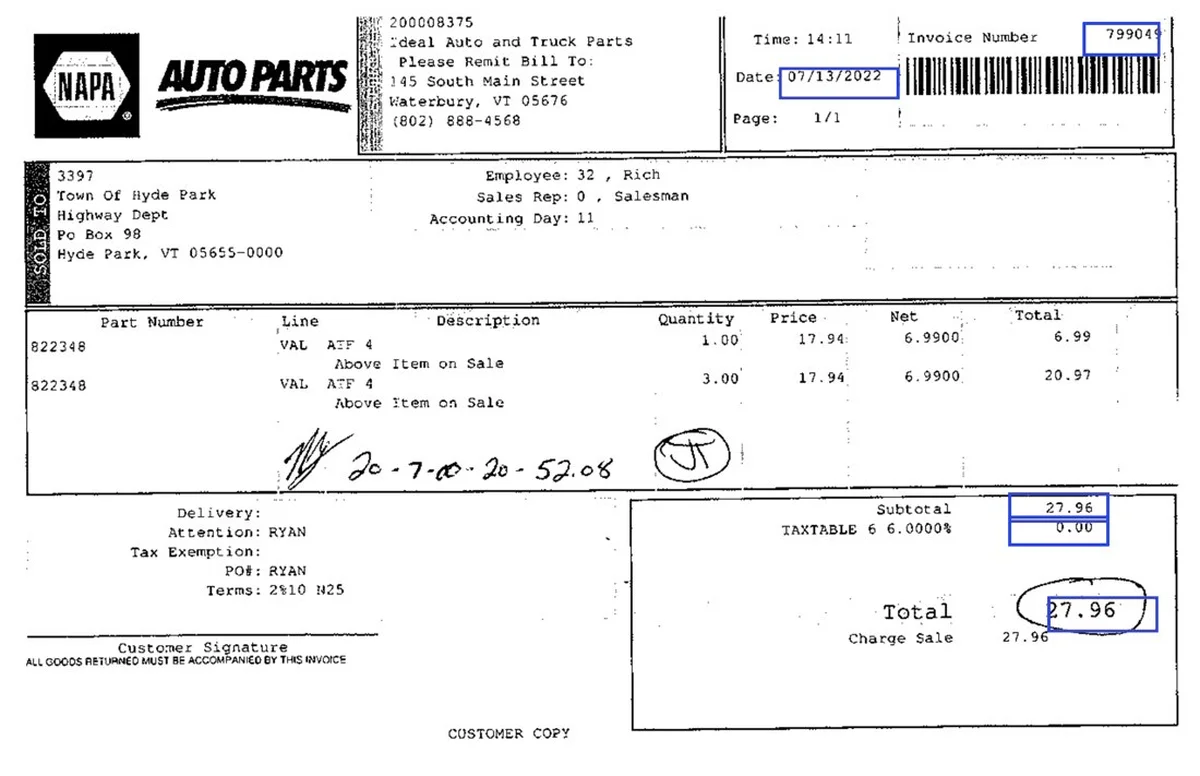 Ideal Auto, 2022
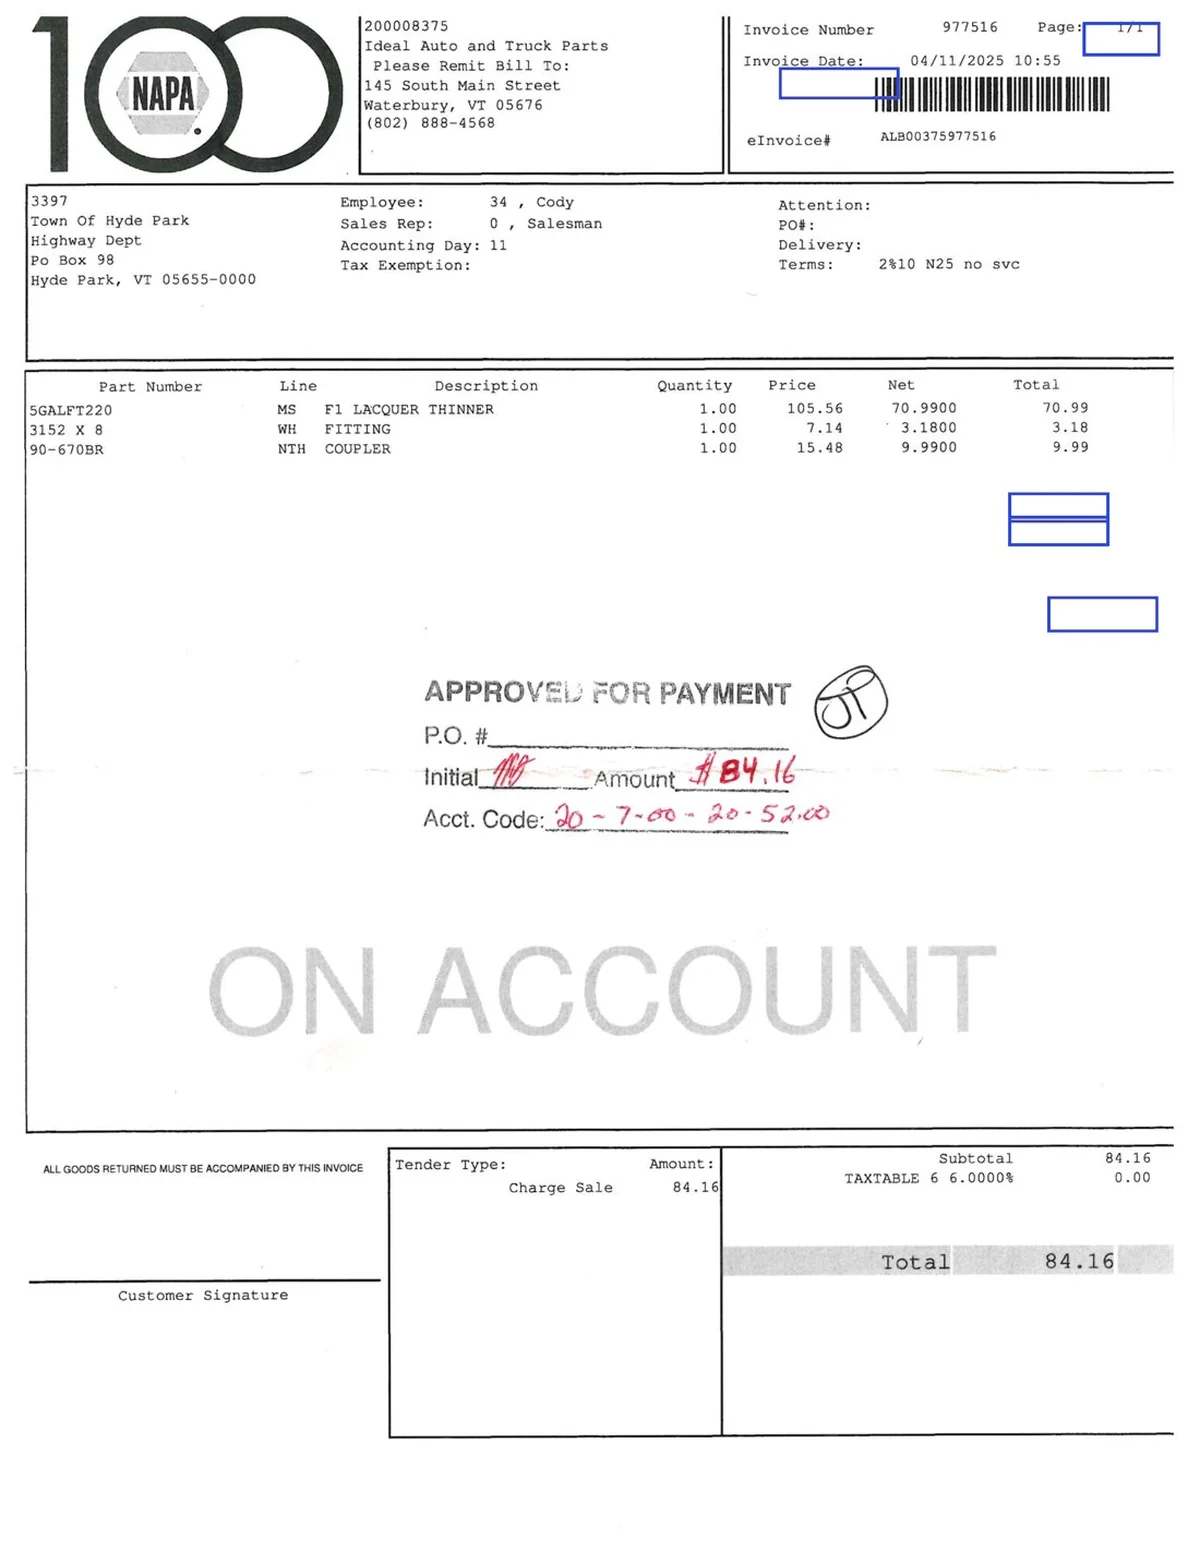 Same vendor, 2025 redesign
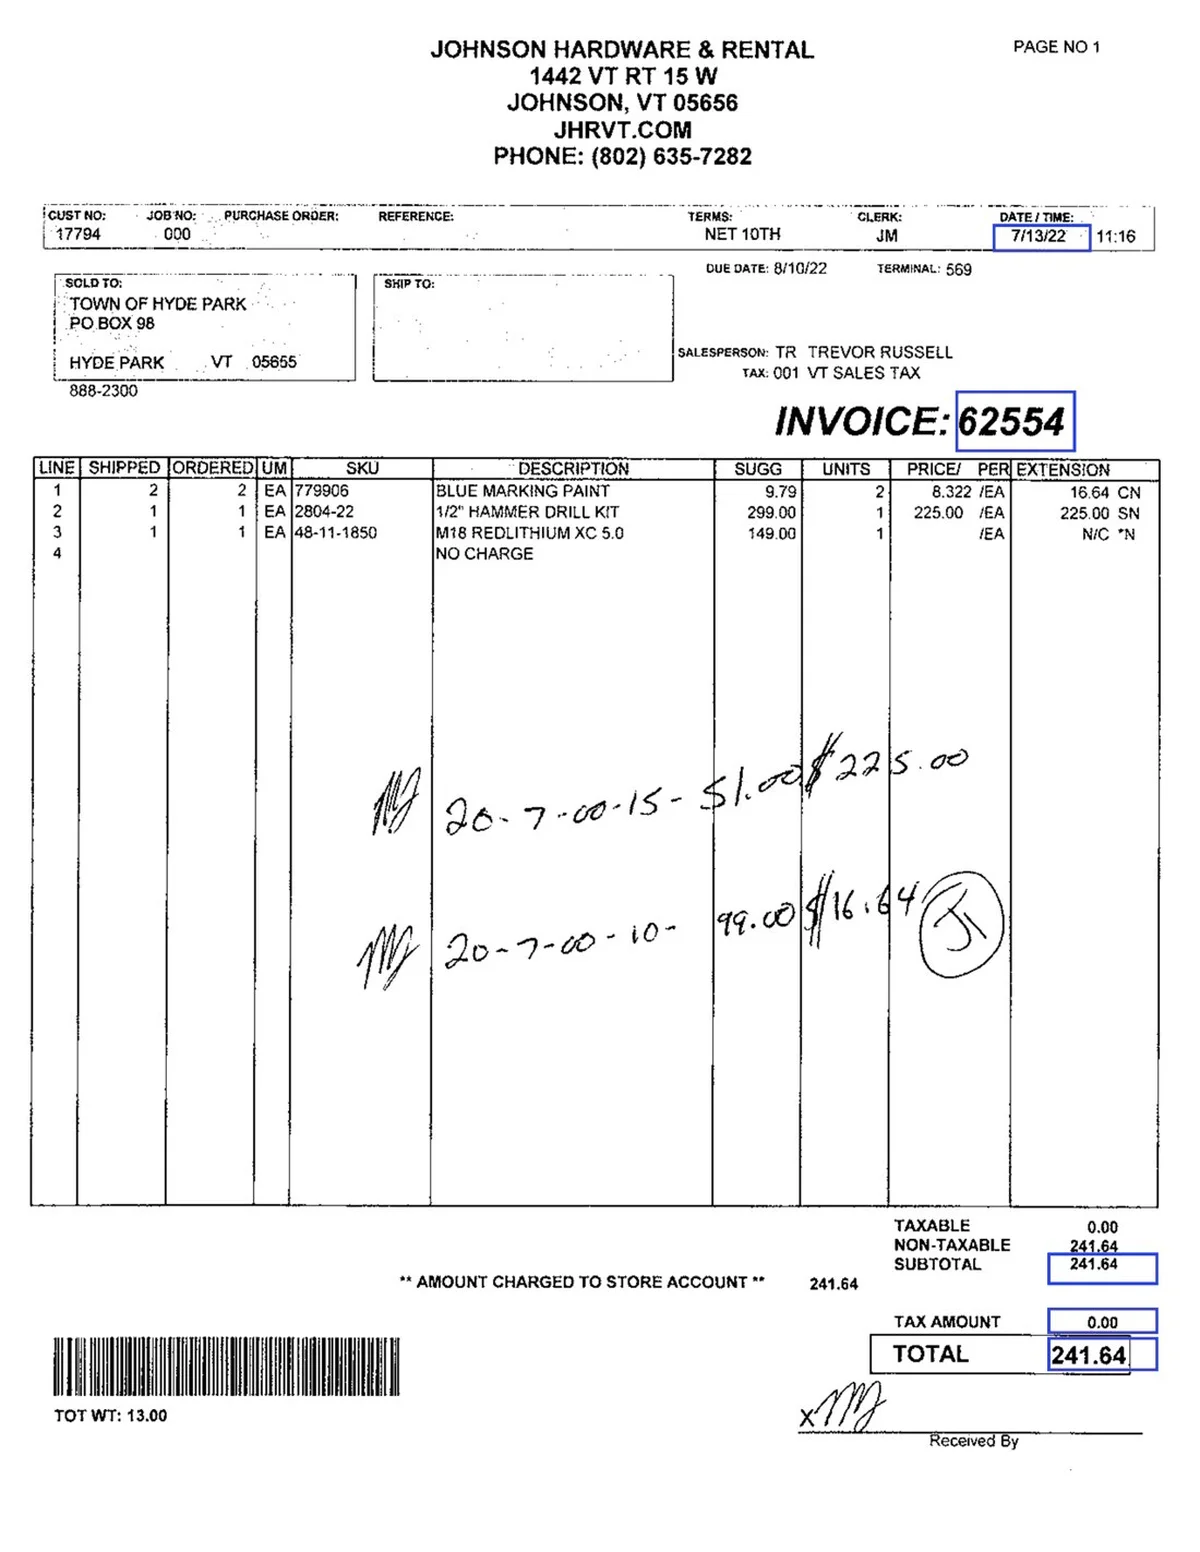 Johnson Hardware
Ideal Auto, 2022. The layout the template was drawn for. Template OCR got 4 of 5 fields right. Lens got 5 of 5.
Field | Template OCR | Lens |
|---|---|---|
Invoice no. | 799046 | 799049 |
Date | 2022-07-13 | 2022-07-13 |
Subtotal | 27.96 | 27.96 |
Tax | 0.00 | 0.00 |
Total | 27.96 | 27.96 |
Same vendor, 2025 redesign. Same template, new layout. The boxes land on empty space. Template OCR got 0 of 5 fields right. Lens got 5 of 5.
Field | Template OCR | Lens |
|---|---|---|
Invoice no. | / | 977516 |
Date | blank | 2025-04-11 |
Subtotal | blank | 84.16 |
Tax | blank | 0.00 |
Total | blank | 84.16 |
Johnson Hardware. A second template, drawn for this layout. Template OCR got 4 of 5 fields right. Lens got 5 of 5.
Field | Template OCR | Lens |
|---|---|---|
Invoice no. | 62554 | 62554 |
Date | blank | 2022-07-13 |
Subtotal | 241.64 | 241.64 |
Tax | 0.00 | 0.00 |
Total | 241.64 | 241.64 |
This shows how templates fail, not how often.
Language models can read layouts they’ve never seen. They fail in a different way. The output can look right when it isn't, and nothing flags the error, like the $5 line from earlier. When a person reviews every document, this costs time. When no one does, it costs money. In one public case, spoofed emails with new remittance details led a company to wire over $476K to a fraudster (court filing).
A newer wave of document tools is much better than OCR or IDP. But they were designed around a person in the loop, and we needed something designed without one.
Testing on real, public documents
Lens runs in production for Pointer customers. For privacy reasons, this post uses public documents that are similar in shape to the ones Pointer handles.
In each section, the boxes on the pages are the regions Lens found, and the table is what Lens returned. Each section calls out the check Lens passed or the difference it flagged.
Invoices
An AP team might receive thousands of invoices a month from different vendors. A single vendor often uses several layouts. The usual fix is one template per vendor, and someone keys the invoice by hand when the template breaks.
The question we hear most from customers is what happens when their invoices come in different formats.
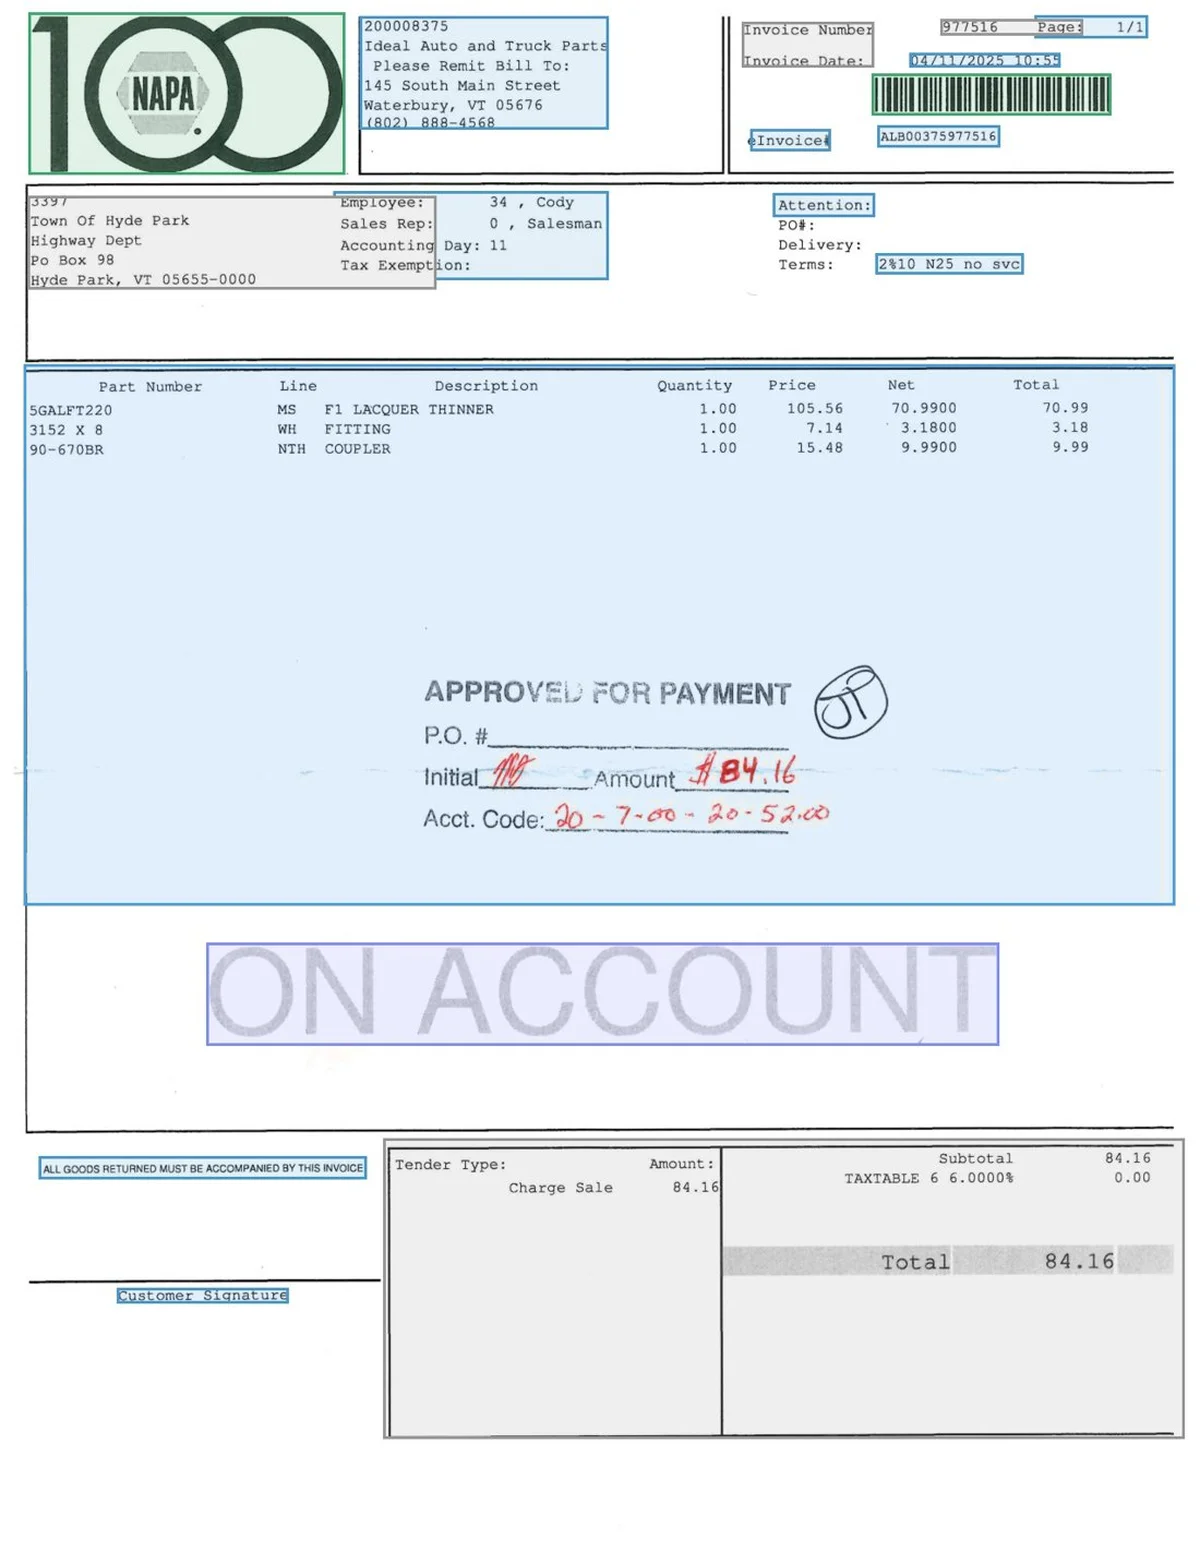
This set includes the invoices from the OCR comparison above. One is a 2022 dot-matrix print scanned in black and white. Another is the same auto-parts vendor's redesigned 2025 template. The other two, a propane delivery and a hardware store receipt, carry handwritten approvals and notes. Source: public accounts-payable records.
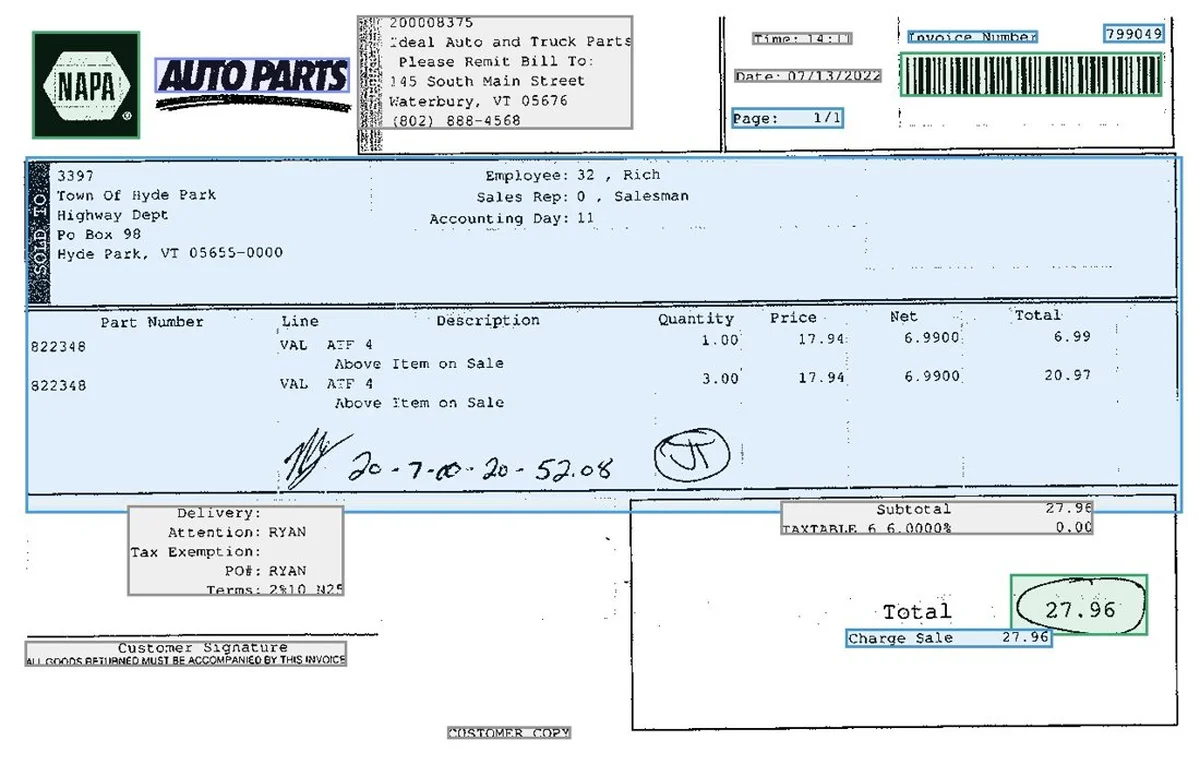 Auto parts, 2022
 Same vendor, 2025
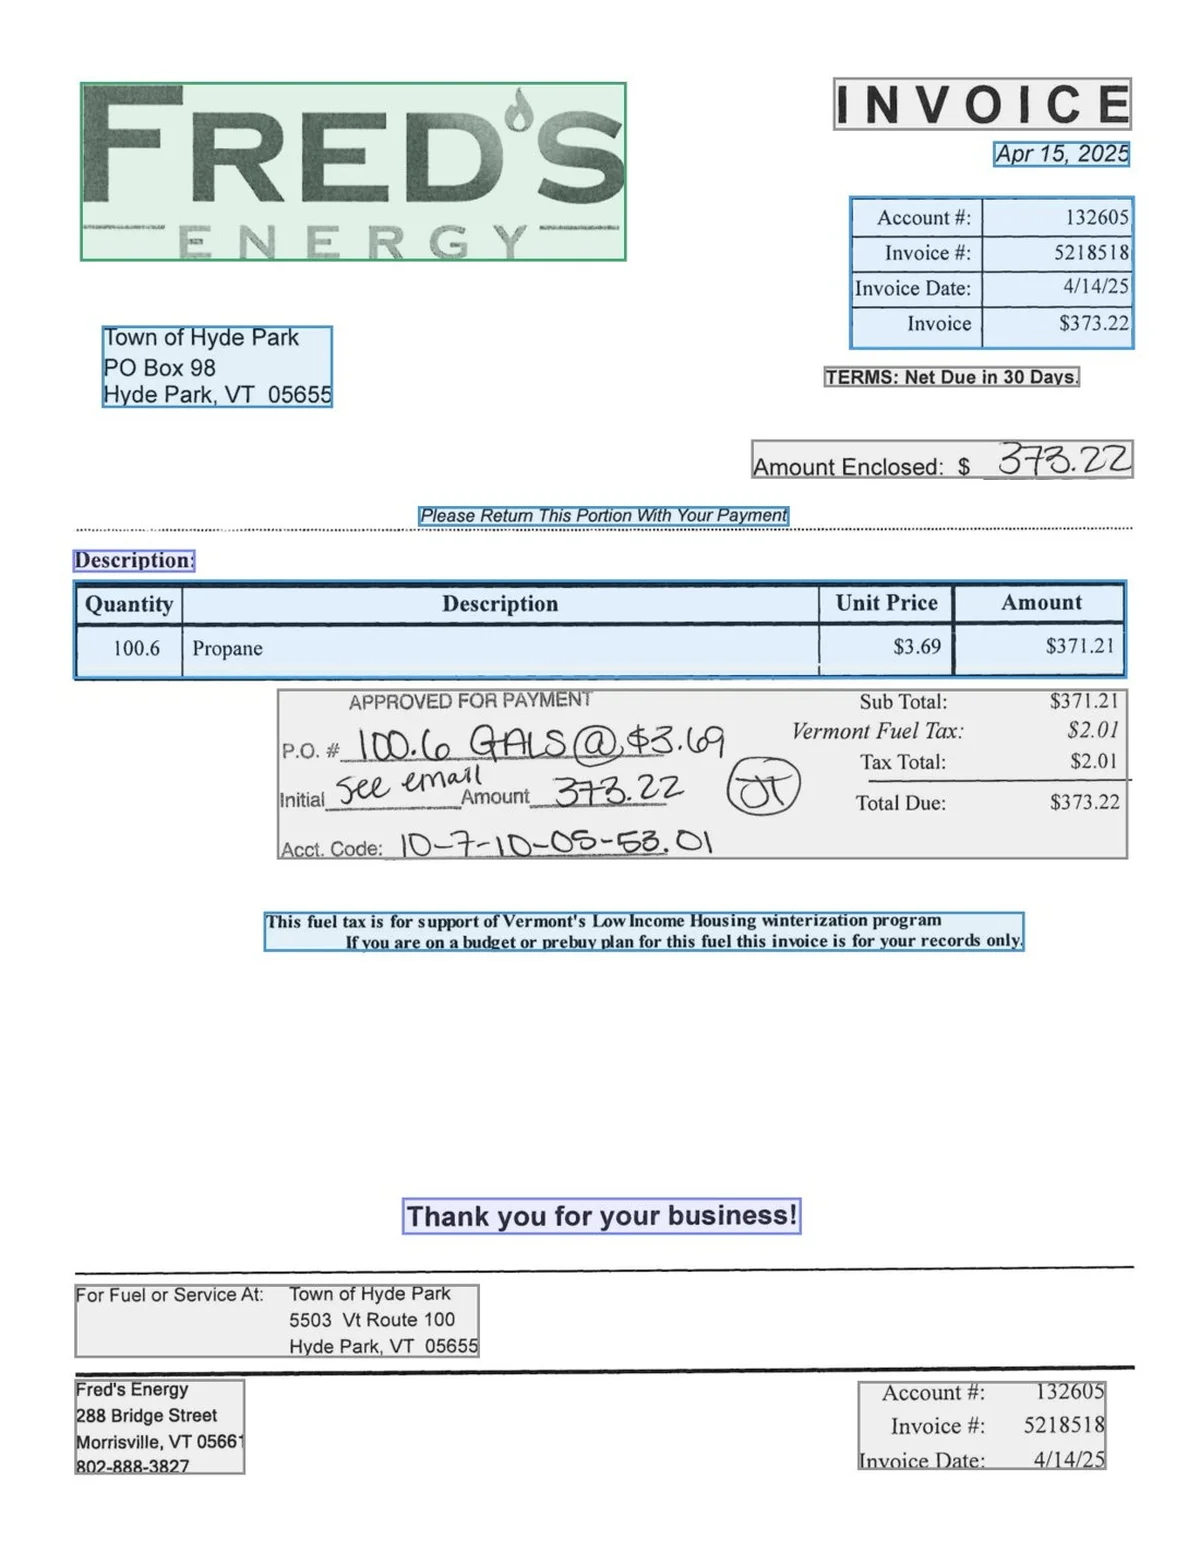 Propane delivery
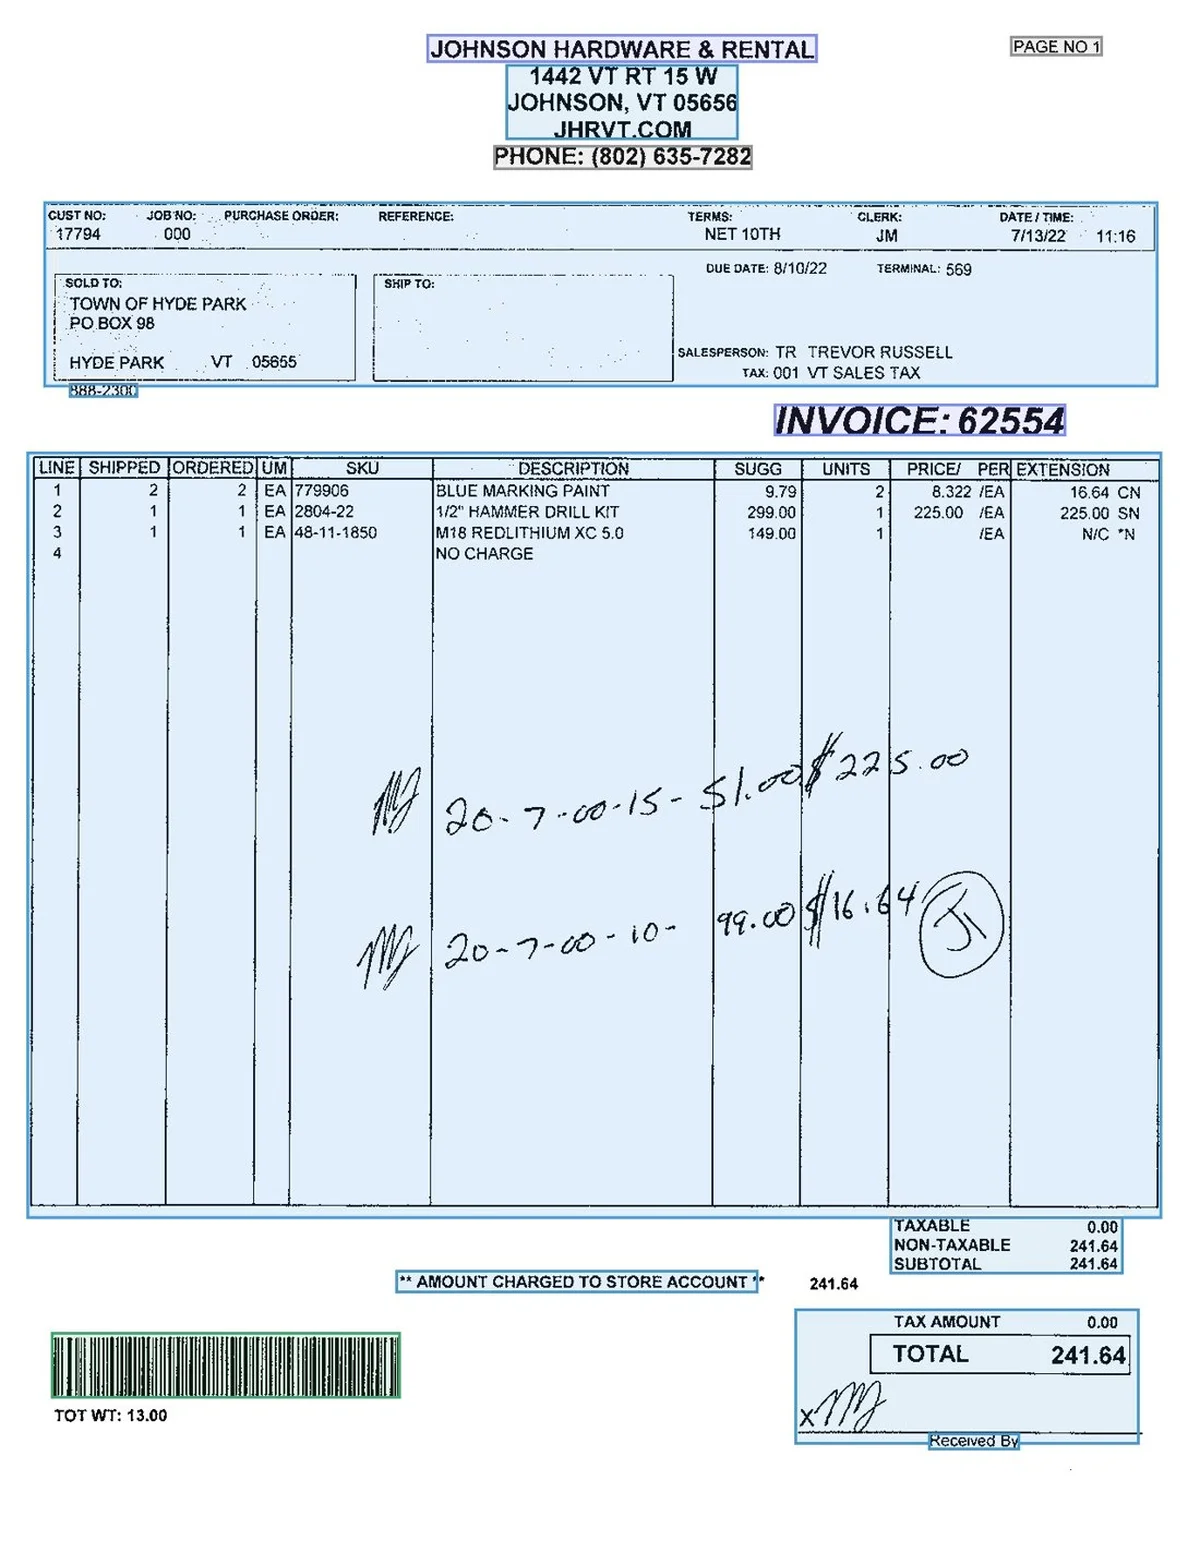 Hardware store
Auto parts, 2022 | Same vendor, 2025 | Propane delivery | Hardware store | |
|---|---|---|---|---|
Layout | Dot-matrix print, scanned in black and white | New template, color scan | One line, handwritten approval | Point-of-sale print, handwritten notes |
Vendor | Ideal Auto and Truck Parts | Ideal Auto and Truck Parts | Fred's Energy | Johnson Hardware & Rental |
Invoice no. | 799049 | 977516 | 5218518 | 62554 |
Date | 2022-07-13 | 2025-04-11 | 2025-04-14 | 2022-07-13 |
Total | 27.96 | 84.16 | 373.22 | 241.64 |
Adds up | 6.99 + 20.97 = 27.96 | 70.99 + 3.18 + 9.99 = 84.16 | 371.21 + 2.01 tax = 373.22 | 16.64 + 225.00 + 0.00 = 241.64 |
Lens returned the same fields from all four layouts, and each total adds up from the amounts on the page.
Bank statements
Reconciliation often starts with a bank statement. A finance team has to match each transaction to the ledger. One missed row, or one debit read as a credit, leaves the account unreconciled. Each bank uses its own layout, and statements often arrive as scans.
One of these statements has separate debit and credit columns with a running balance. One prints signed amounts sideways. One is a six-page scan with credits and debits in separate sections. Source: public court filings.
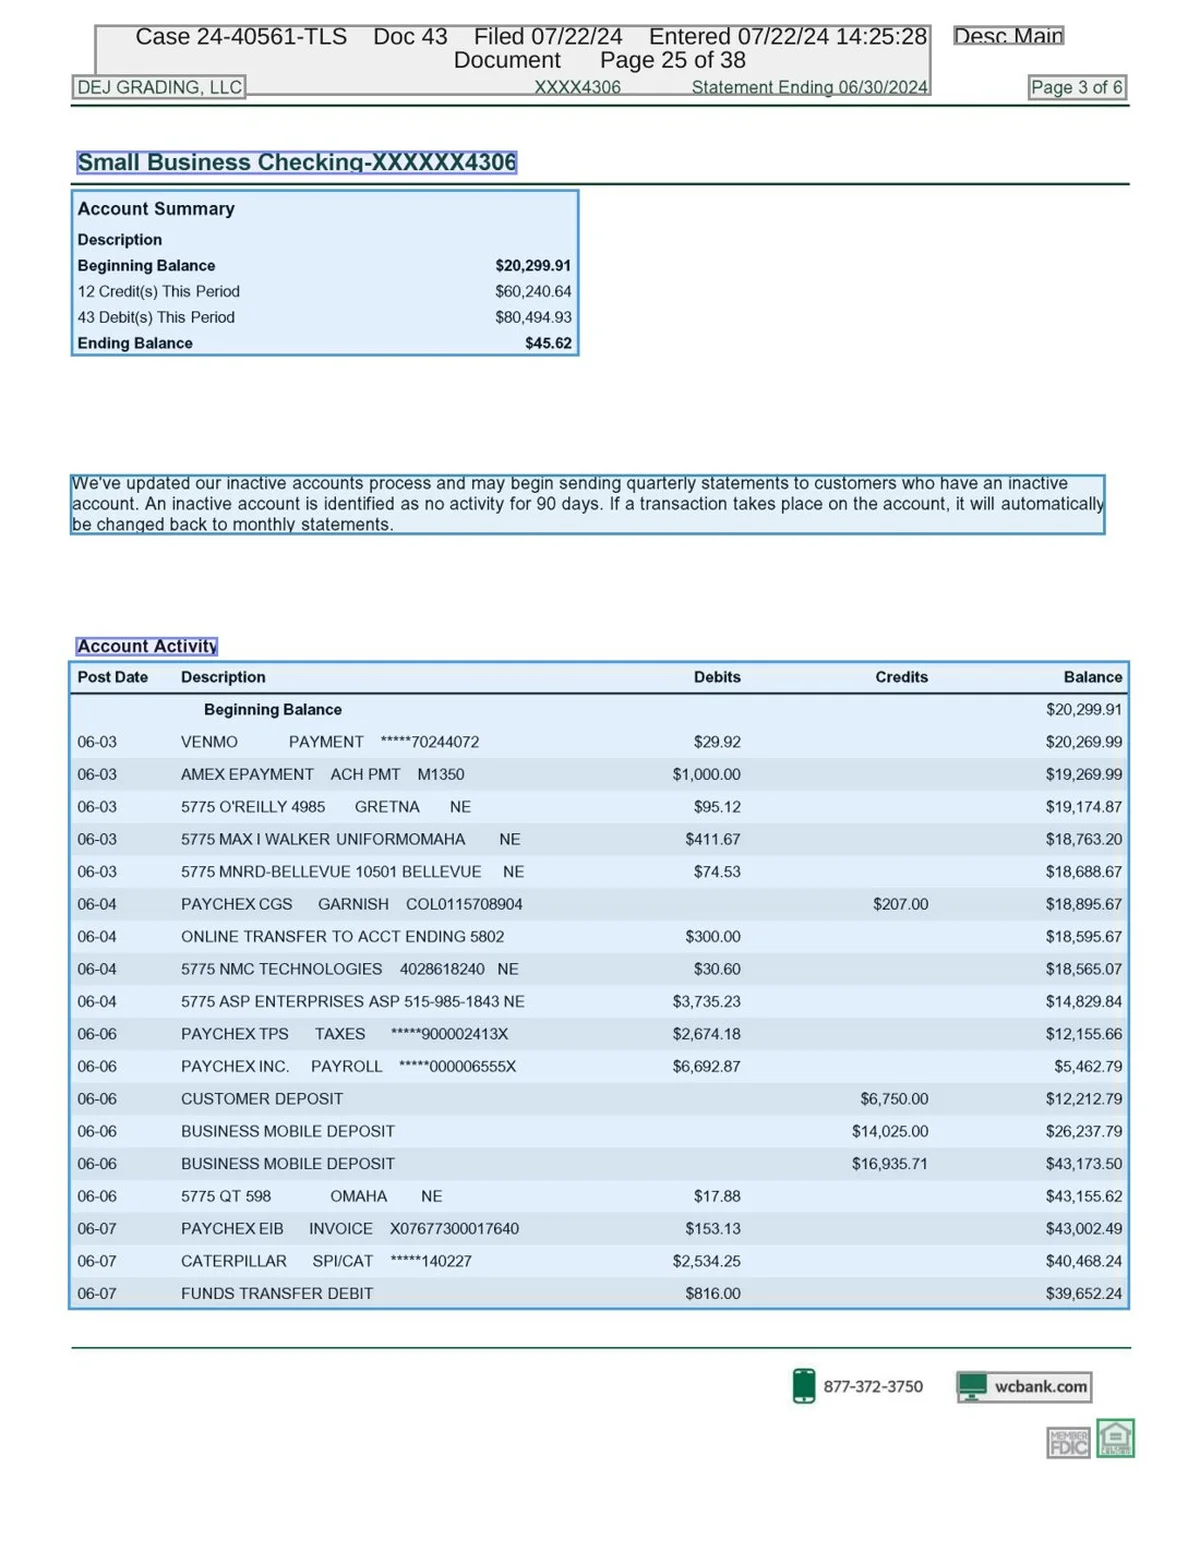 Separate debit and credit columns
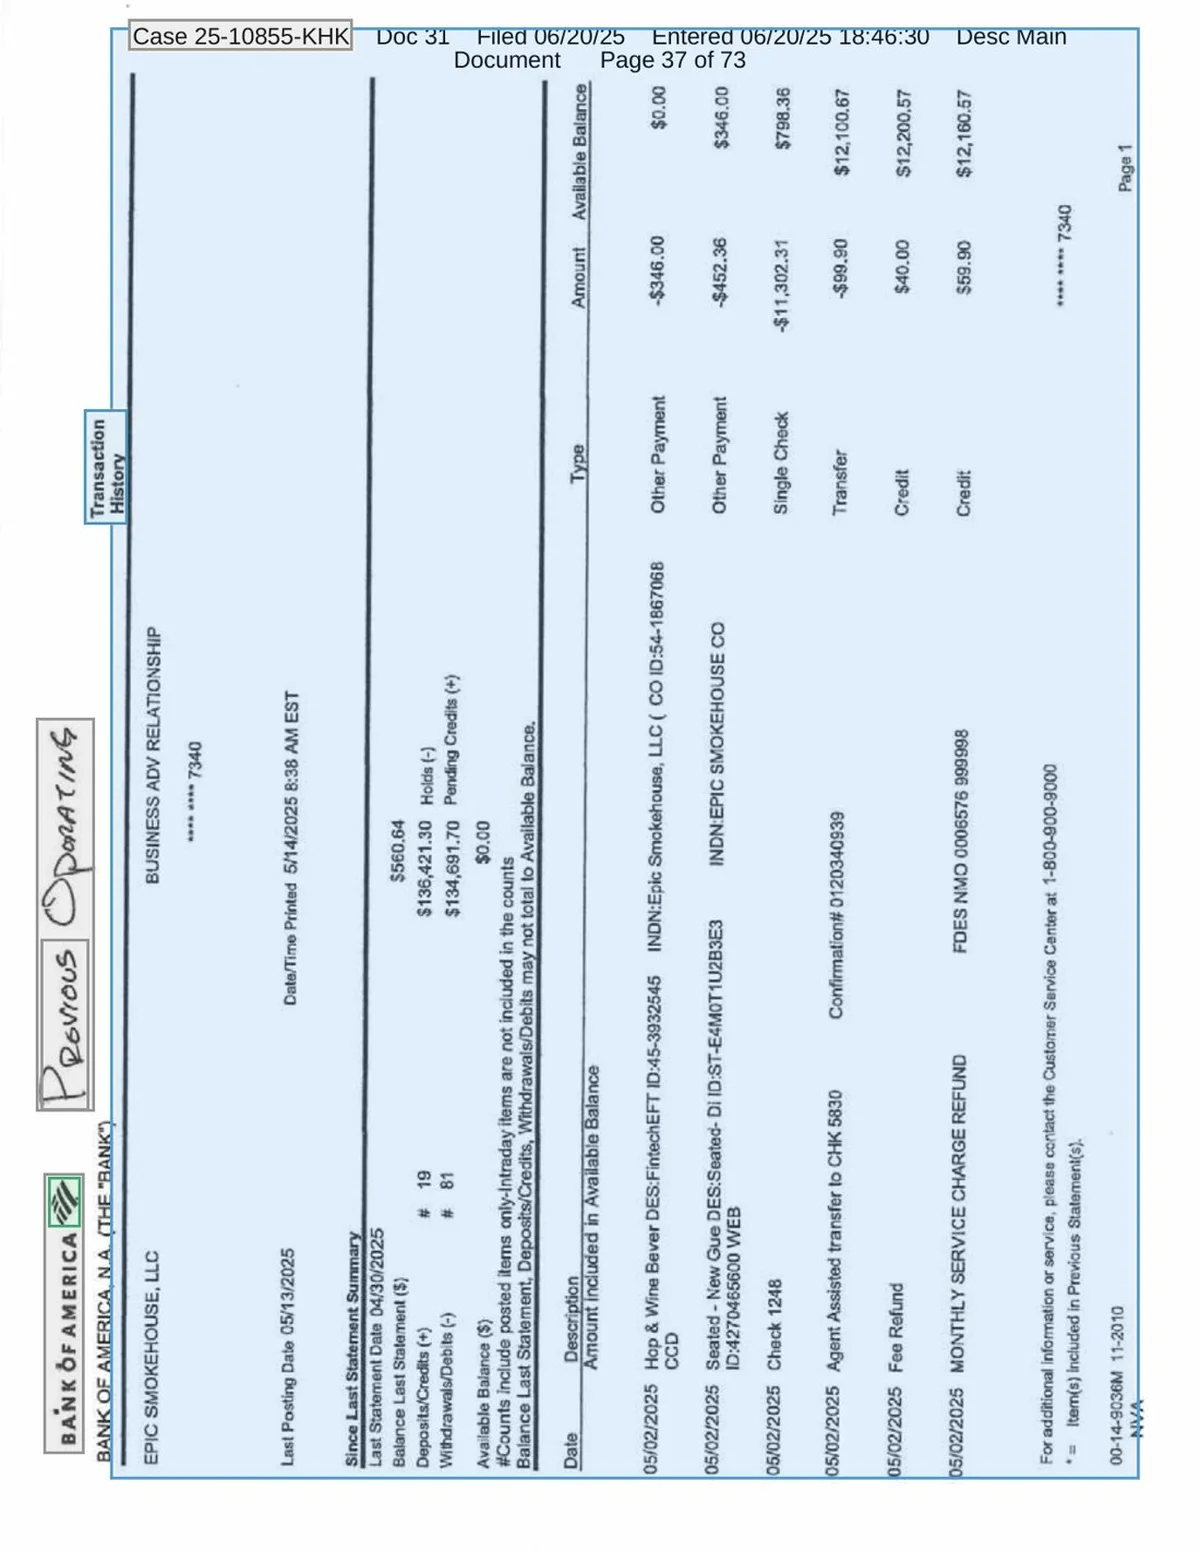 Signed amounts, printed sideways
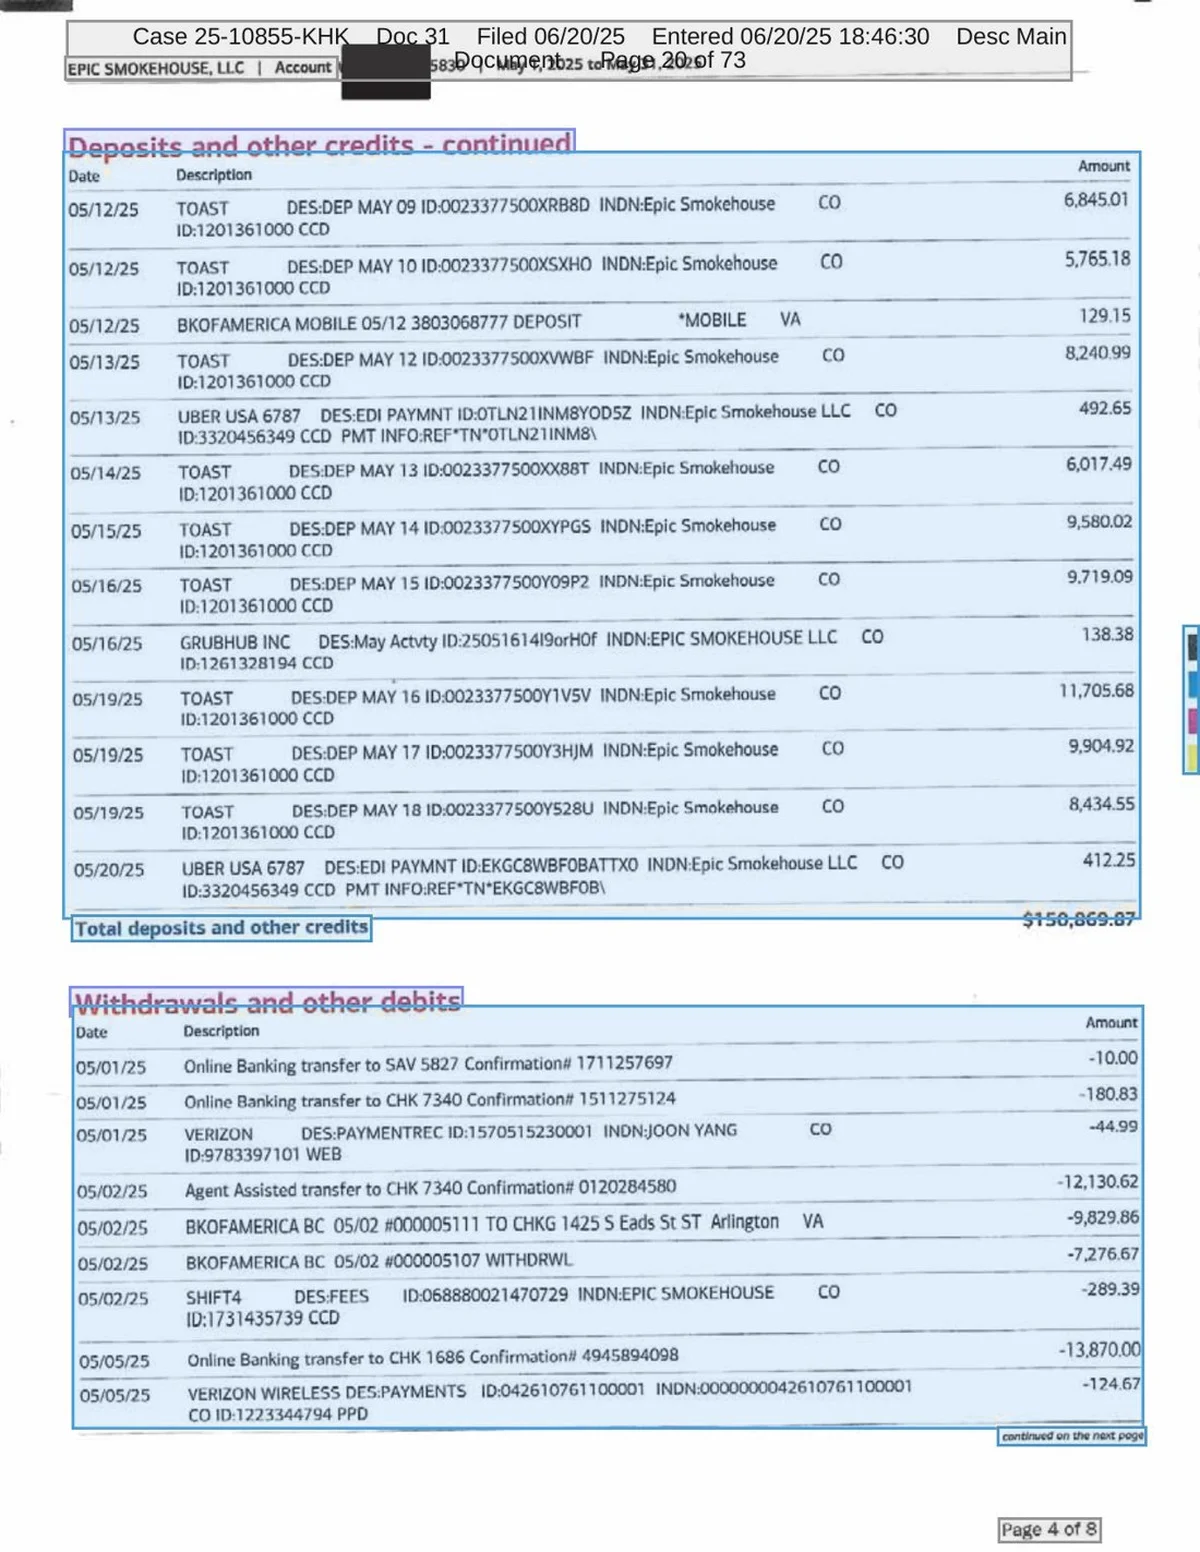 Six-page scan
Separate debit and credit columns | Signed amounts, printed sideways | Six-page scan | |
|---|---|---|---|
Transactions read | 55 | 12 | 59 |
Opening balance | 20,299.91 | 560.64 | 7,844.98 |
Credits in | 60,240.64 | 12,411.35 | 150,869.87 |
Debits out | 80,494.93 | 12,971.99 | 158,714.85 |
Closing balance, from the statement | 45.62 | 0.00 | 0.00 |
Opening + credits − debits = closing | Yes | Yes | Yes |
Lens read the date, amount and direction of all 126 transactions correctly. Each statement also reconciles. The opening balance, plus credits, minus debits, equals the closing balance on the statement. One missed row or one flipped debit would break that.
Purchase orders
Before paying an invoice, finance checks it against the purchase order and the supplier's confirmation. If the price changed between them and no one notices, the company overpays.
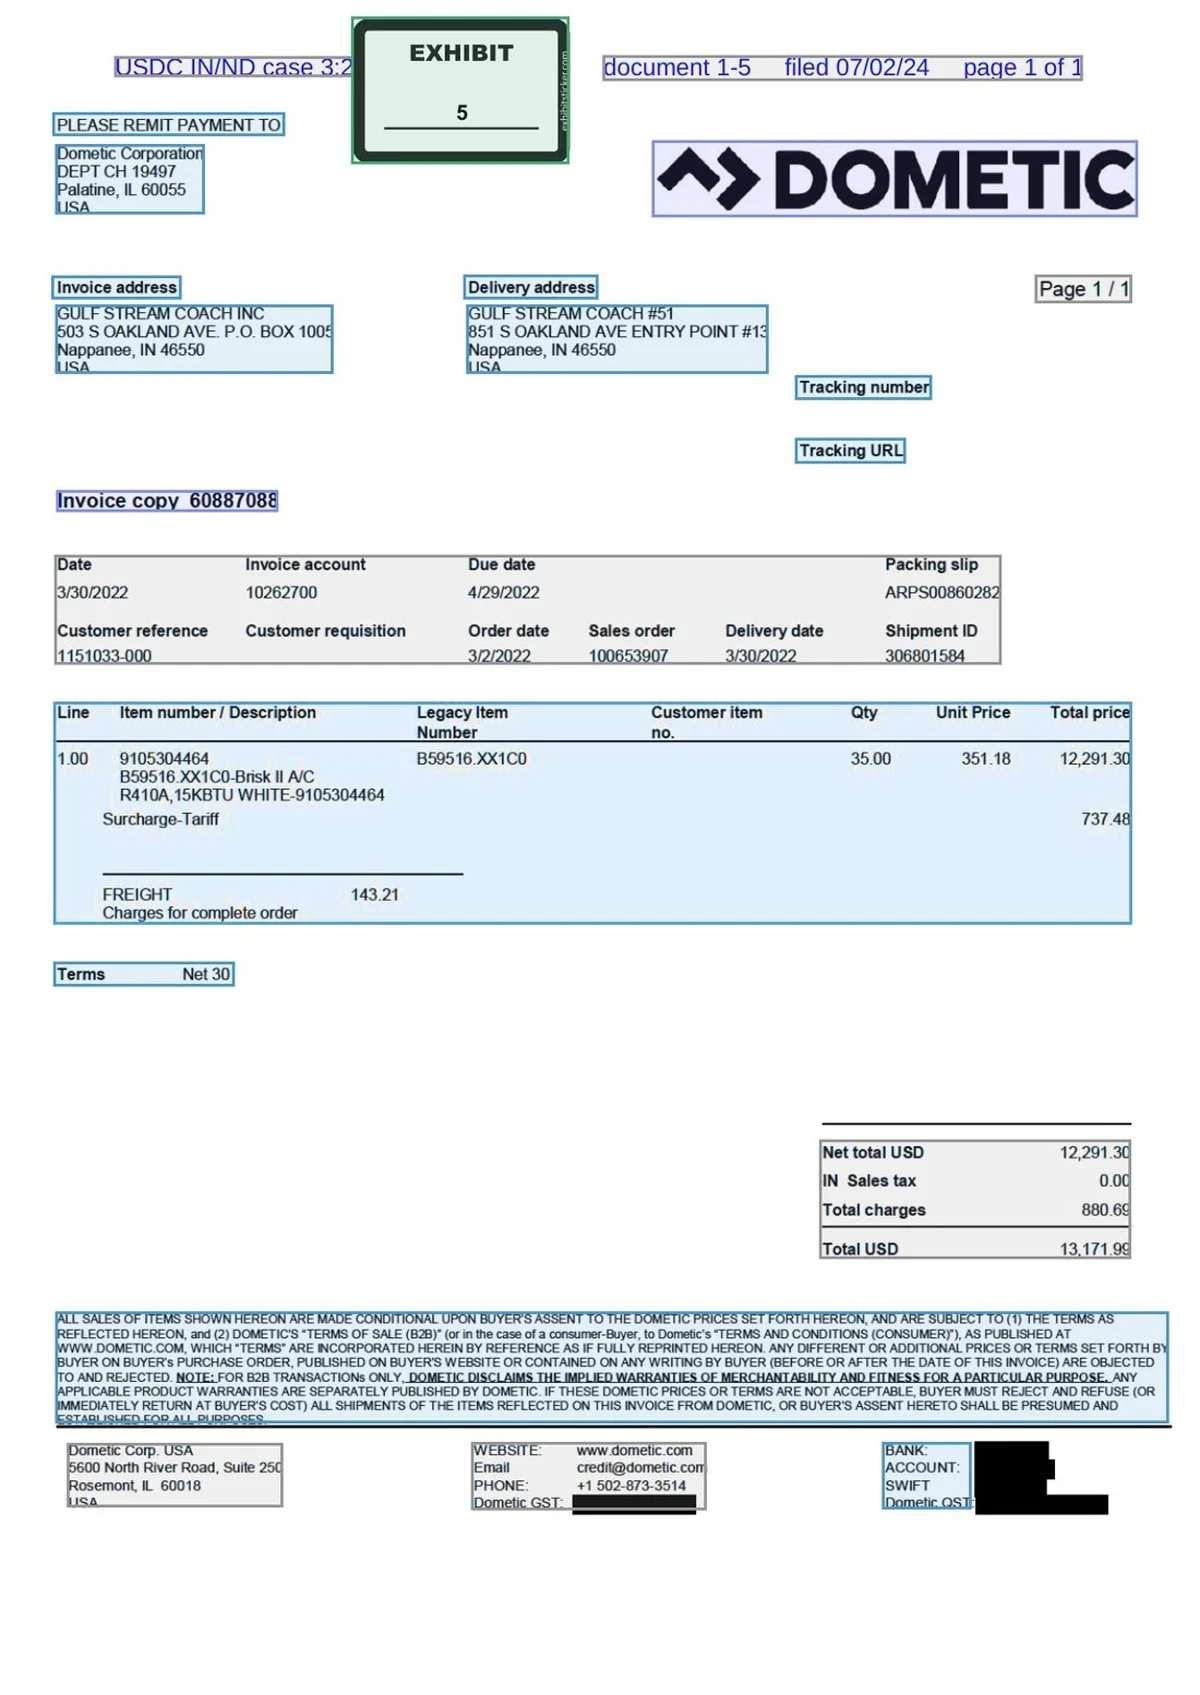
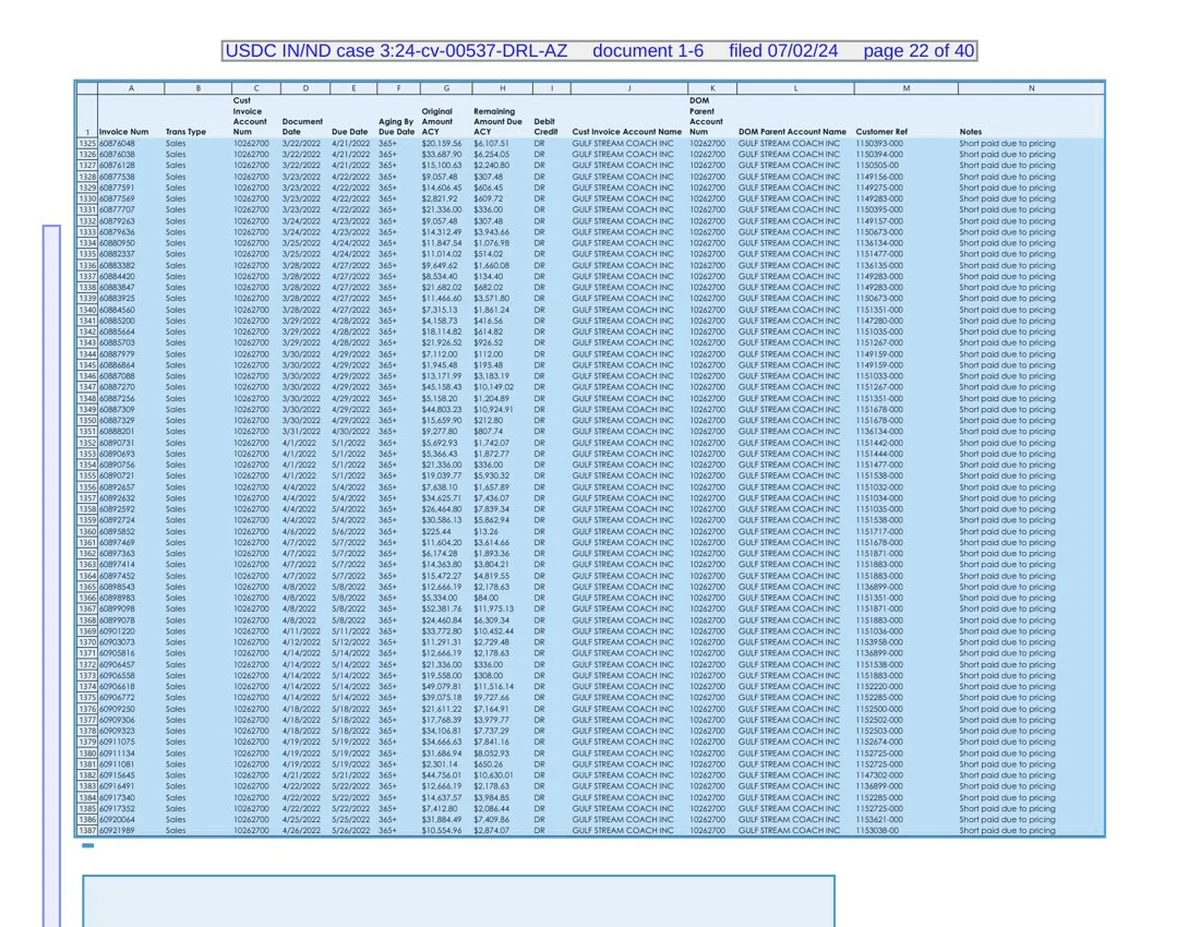
In this commercial dispute from federal court, the supplier's confirmation raised the unit price by 30%, from 269.24 to 351.18. The invoice used the confirmation's price. The buyer short-paid the invoice, and the supplier's books record the gap as "short paid due to pricing." Source: court exhibits from the dispute.
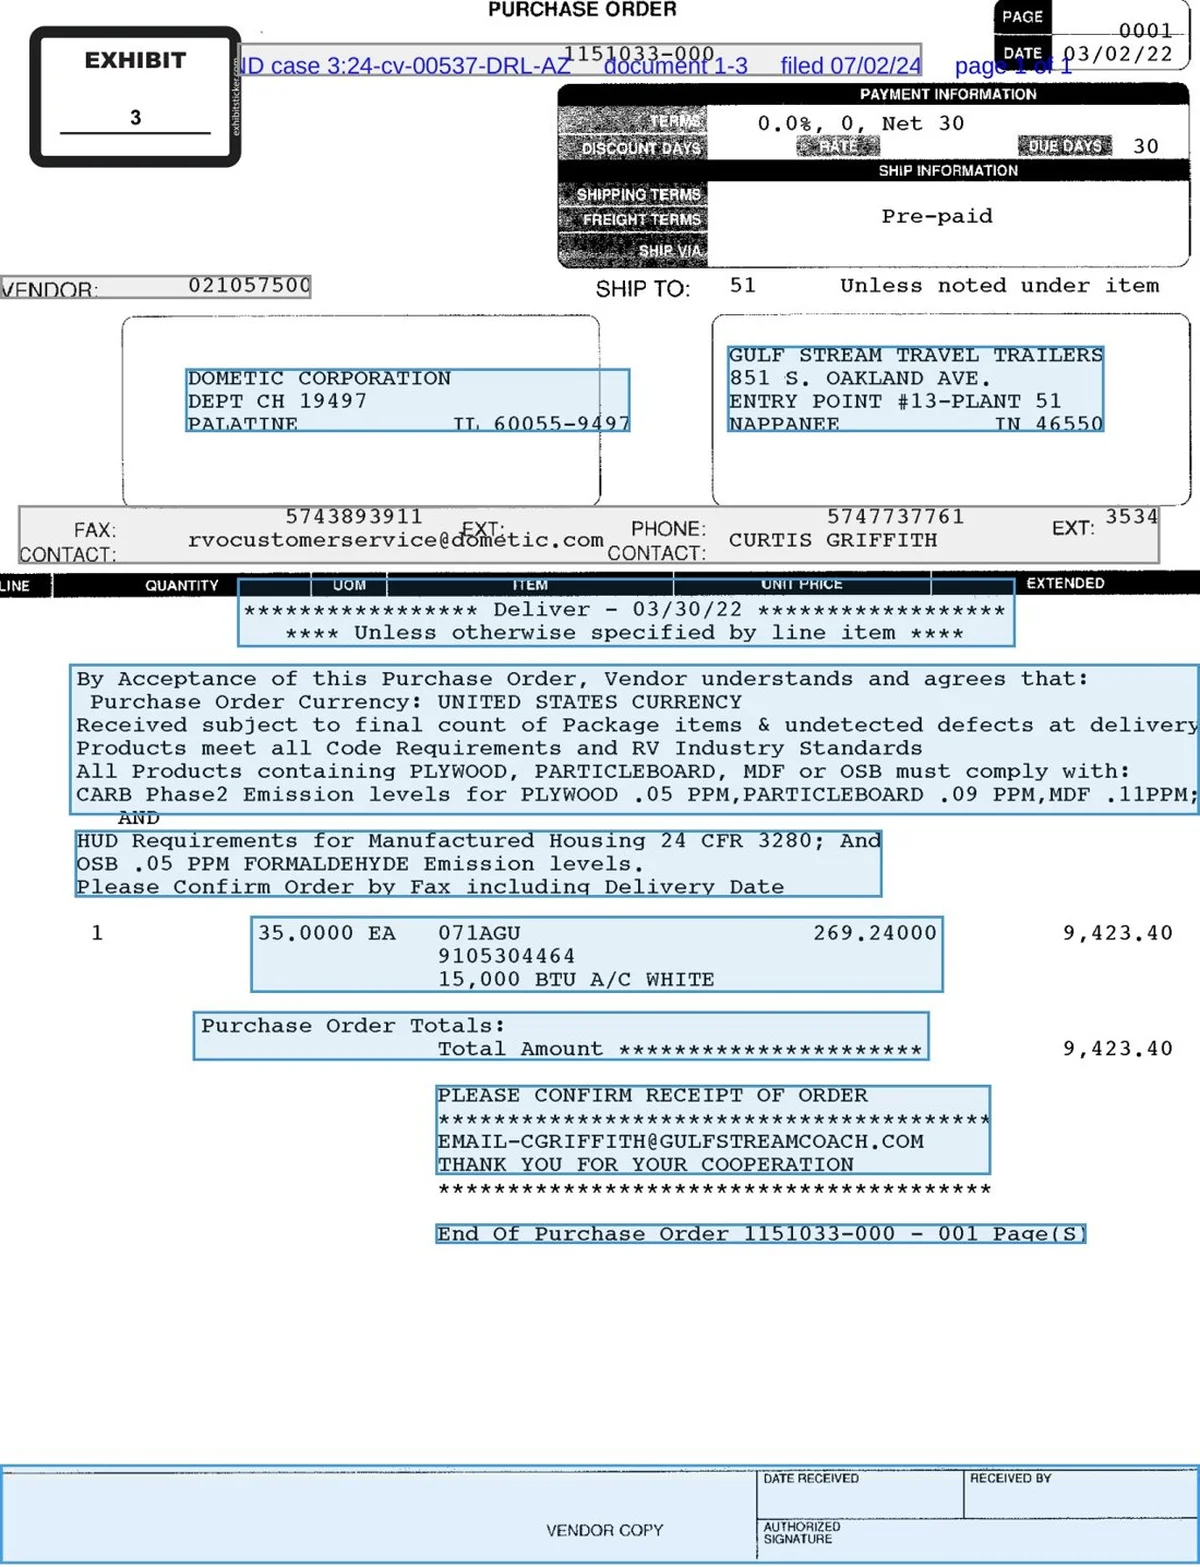 Purchase order, Mar 2
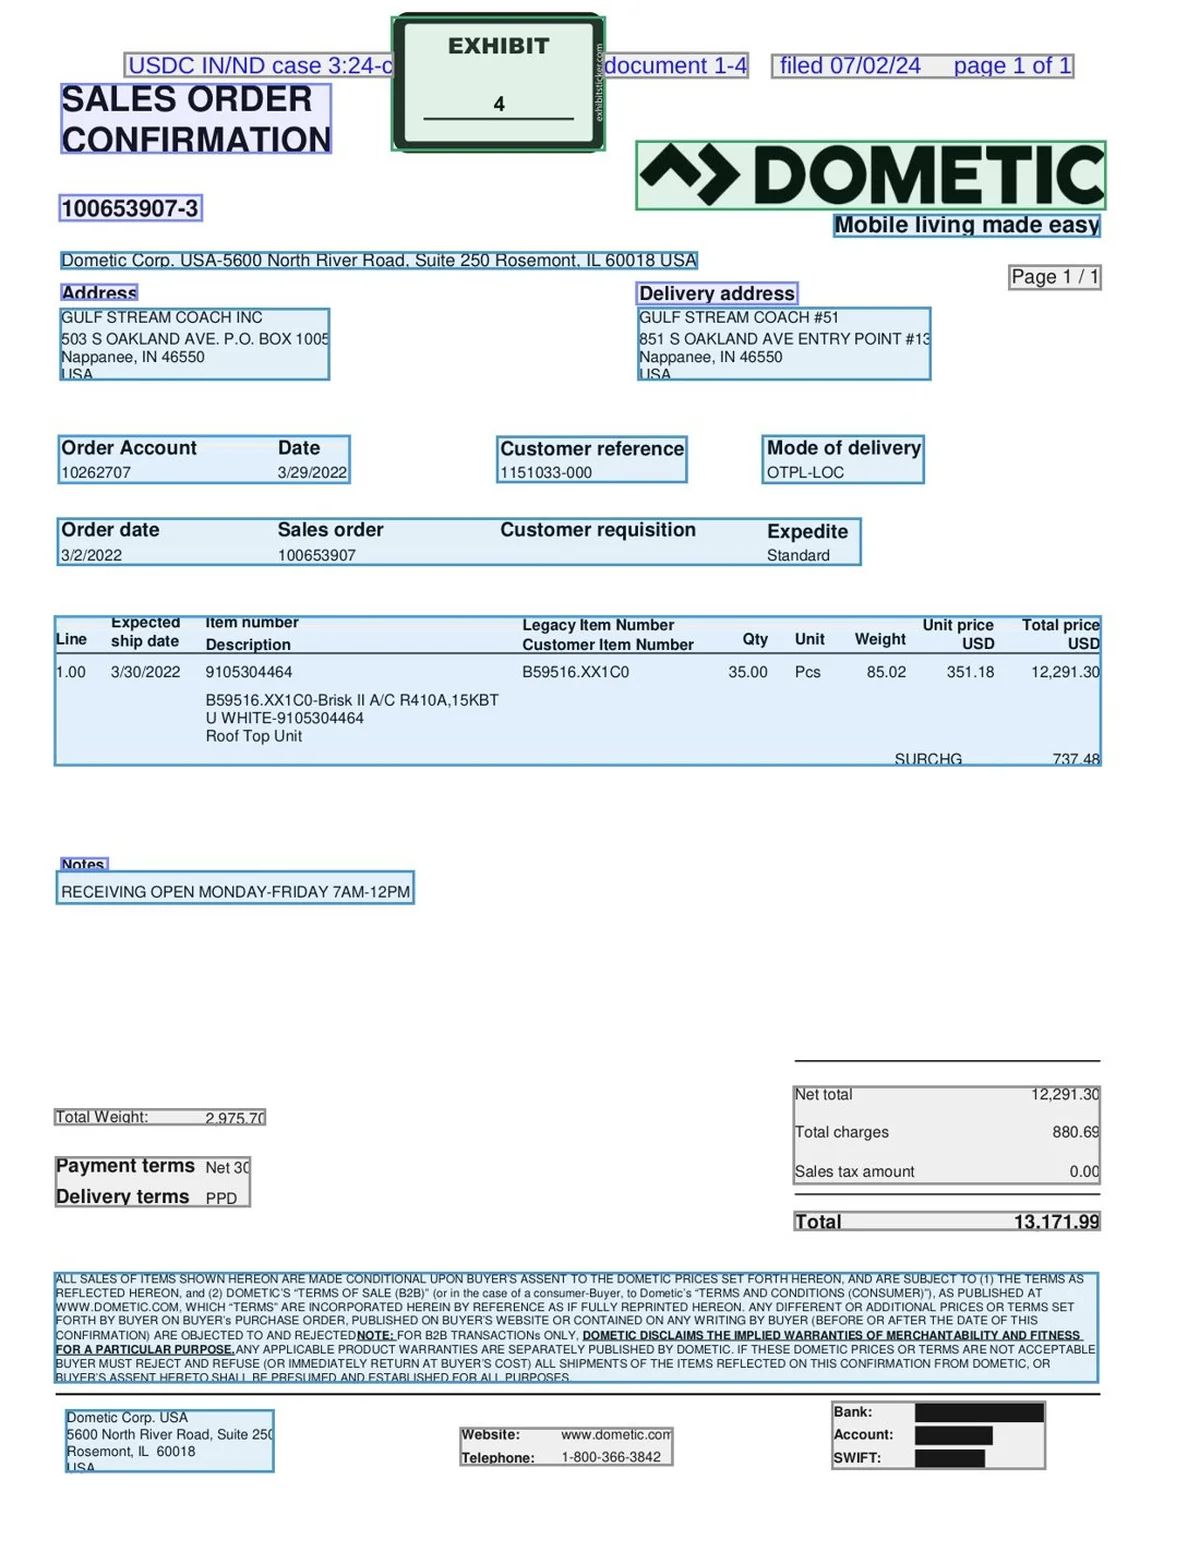 Order confirmation, Mar 29
 Invoice, Mar 30
 Open-invoice report, later
Highlighted numbers changed after the purchase order. Lens read each one as printed.
Purchase order, Mar 2 | Order confirmation, Mar 29 | Invoice, Mar 30 | Open-invoice report, later | |
|---|---|---|---|---|
Unit price | 269.24 | 351.18 | 351.18 | — |
Surcharge | — | 737.48 | 737.48 | — |
Freight | — | — | 143.21 | — |
Total | 9,423.40 | 13,171.99 | 13,171.99 | — |
Still open | — | — | — | 3,183.19 |
Note | — | — | — | Short paid due to pricing |
Lens read all four documents into the same fields, so the price change shows up as a number before payment. The invoice came to 3,748.59 more than the order. Of that, 2,867.90 is the higher price, 737.48 is a surcharge and 143.21 is freight. Pointer's match uses that number to hold the invoice at the agreed price.
Onboarding
Before a bank takes on a customer, or a company takes on a vendor, someone has to check that every document names the same company and owner. Mistakes here can be how payments reach shell companies and how banks get fined.
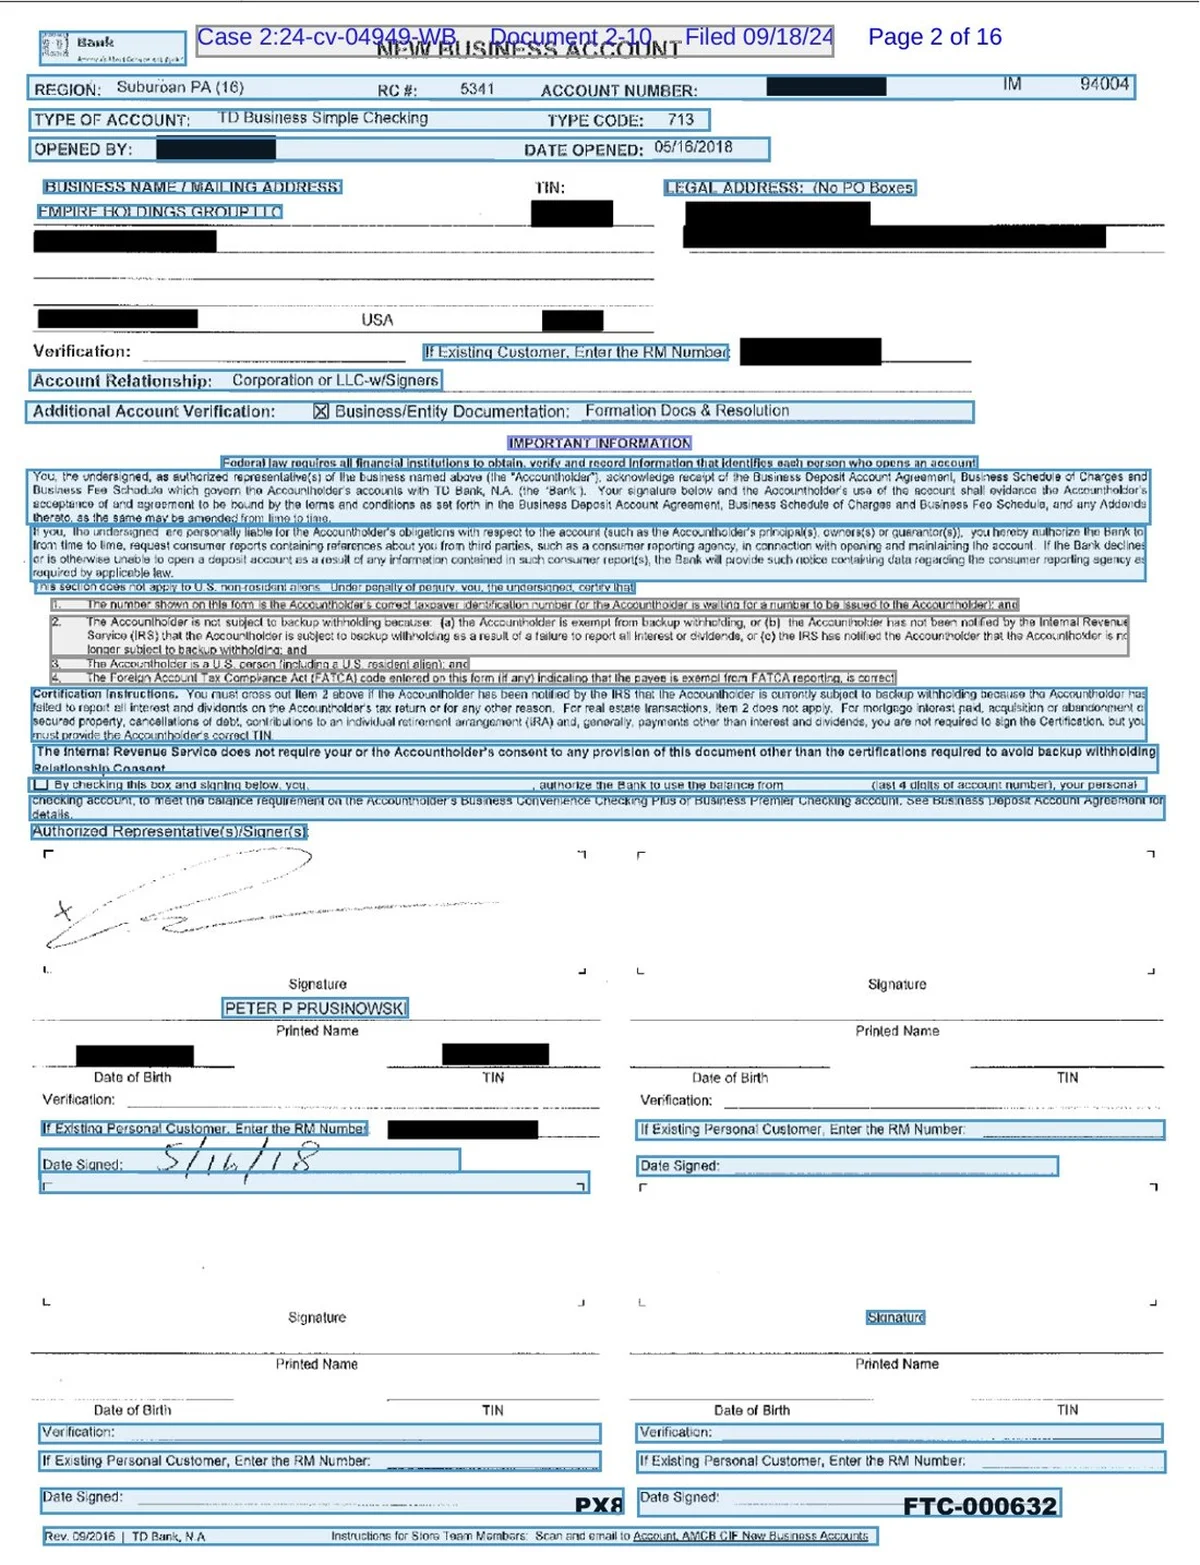
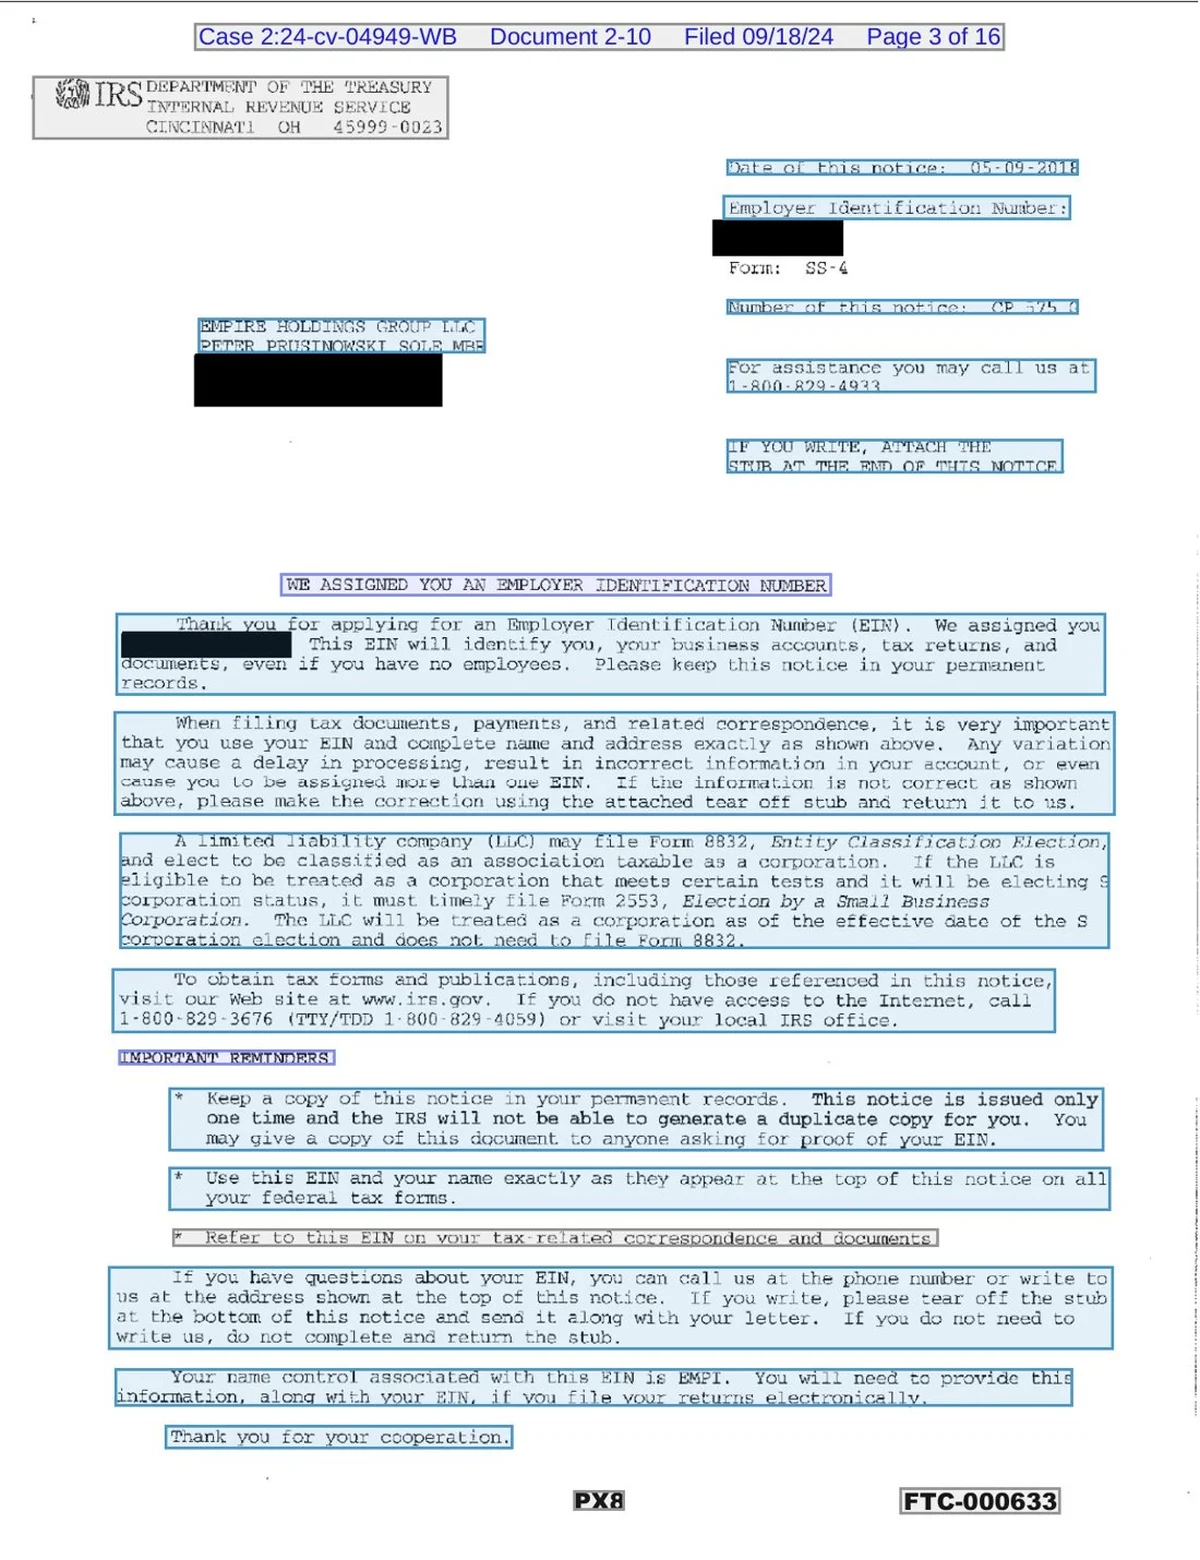
This packet describes one company across five documents. Two were filled out by hand. Source: court exhibits from a federal enforcement case. Black bars are redactions.
 Account-opening form
 IRS EIN notice
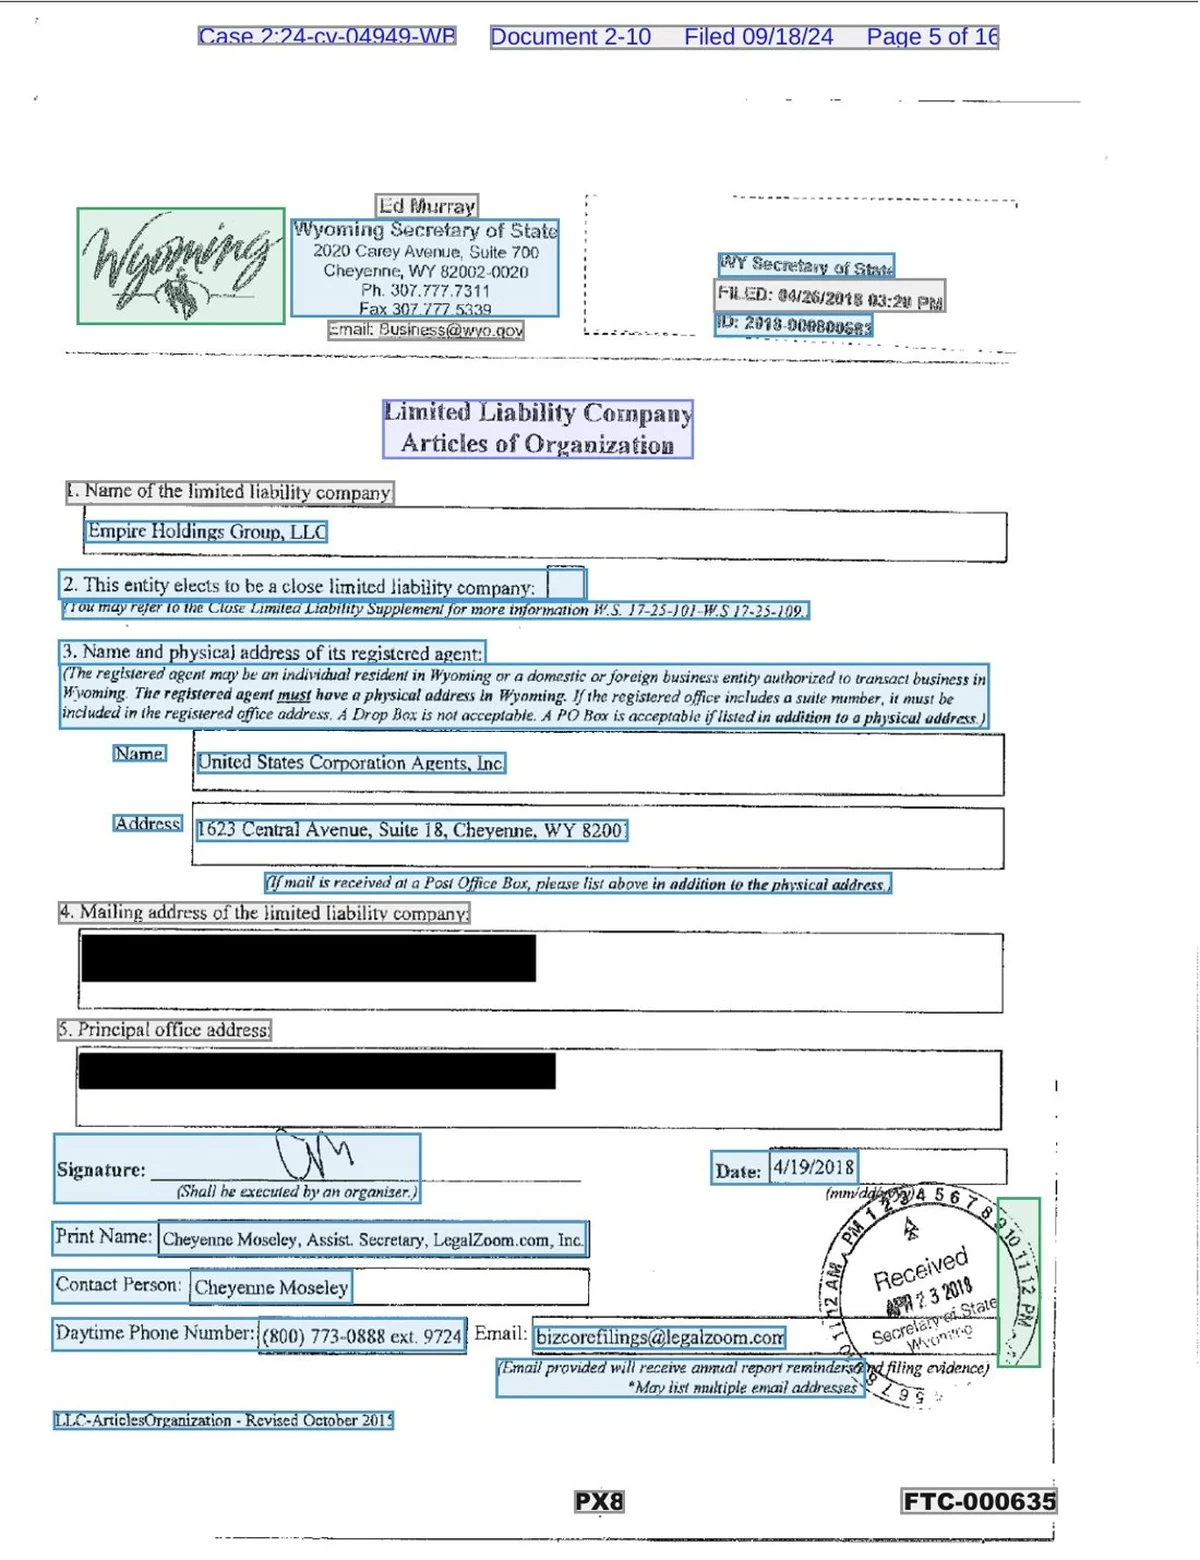 Articles of organization
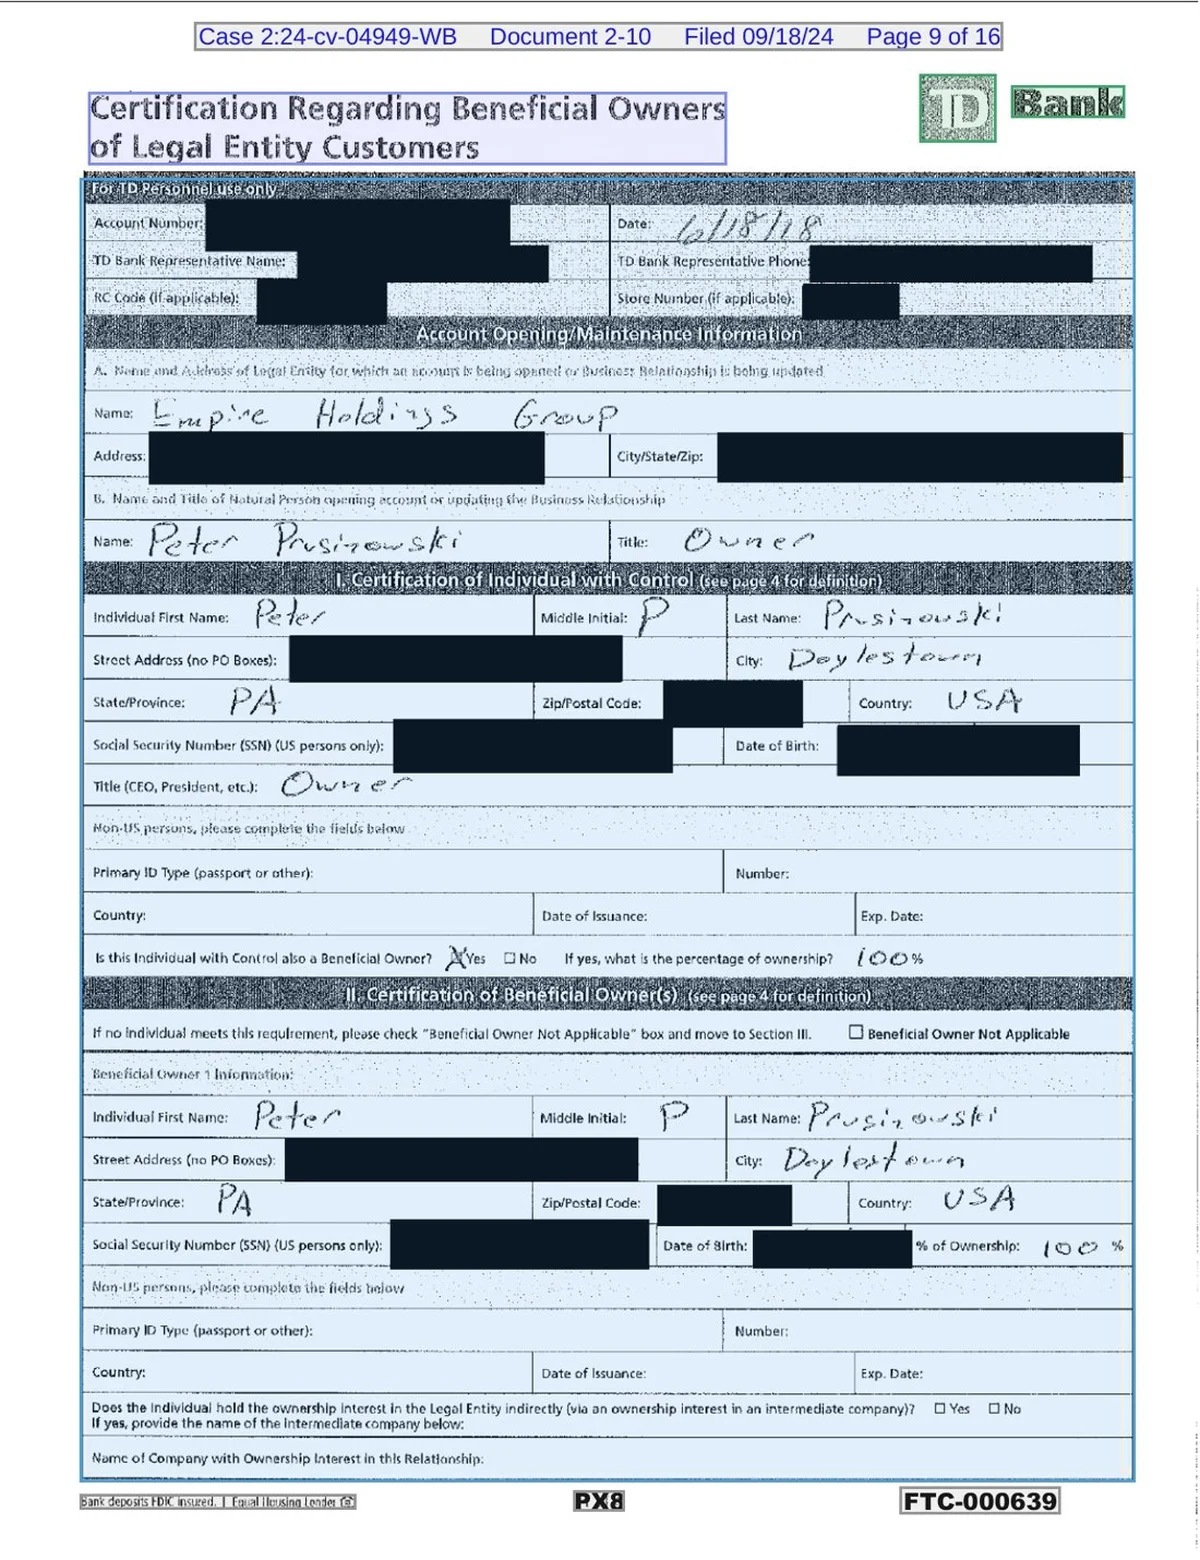 Ownership form, handwritten
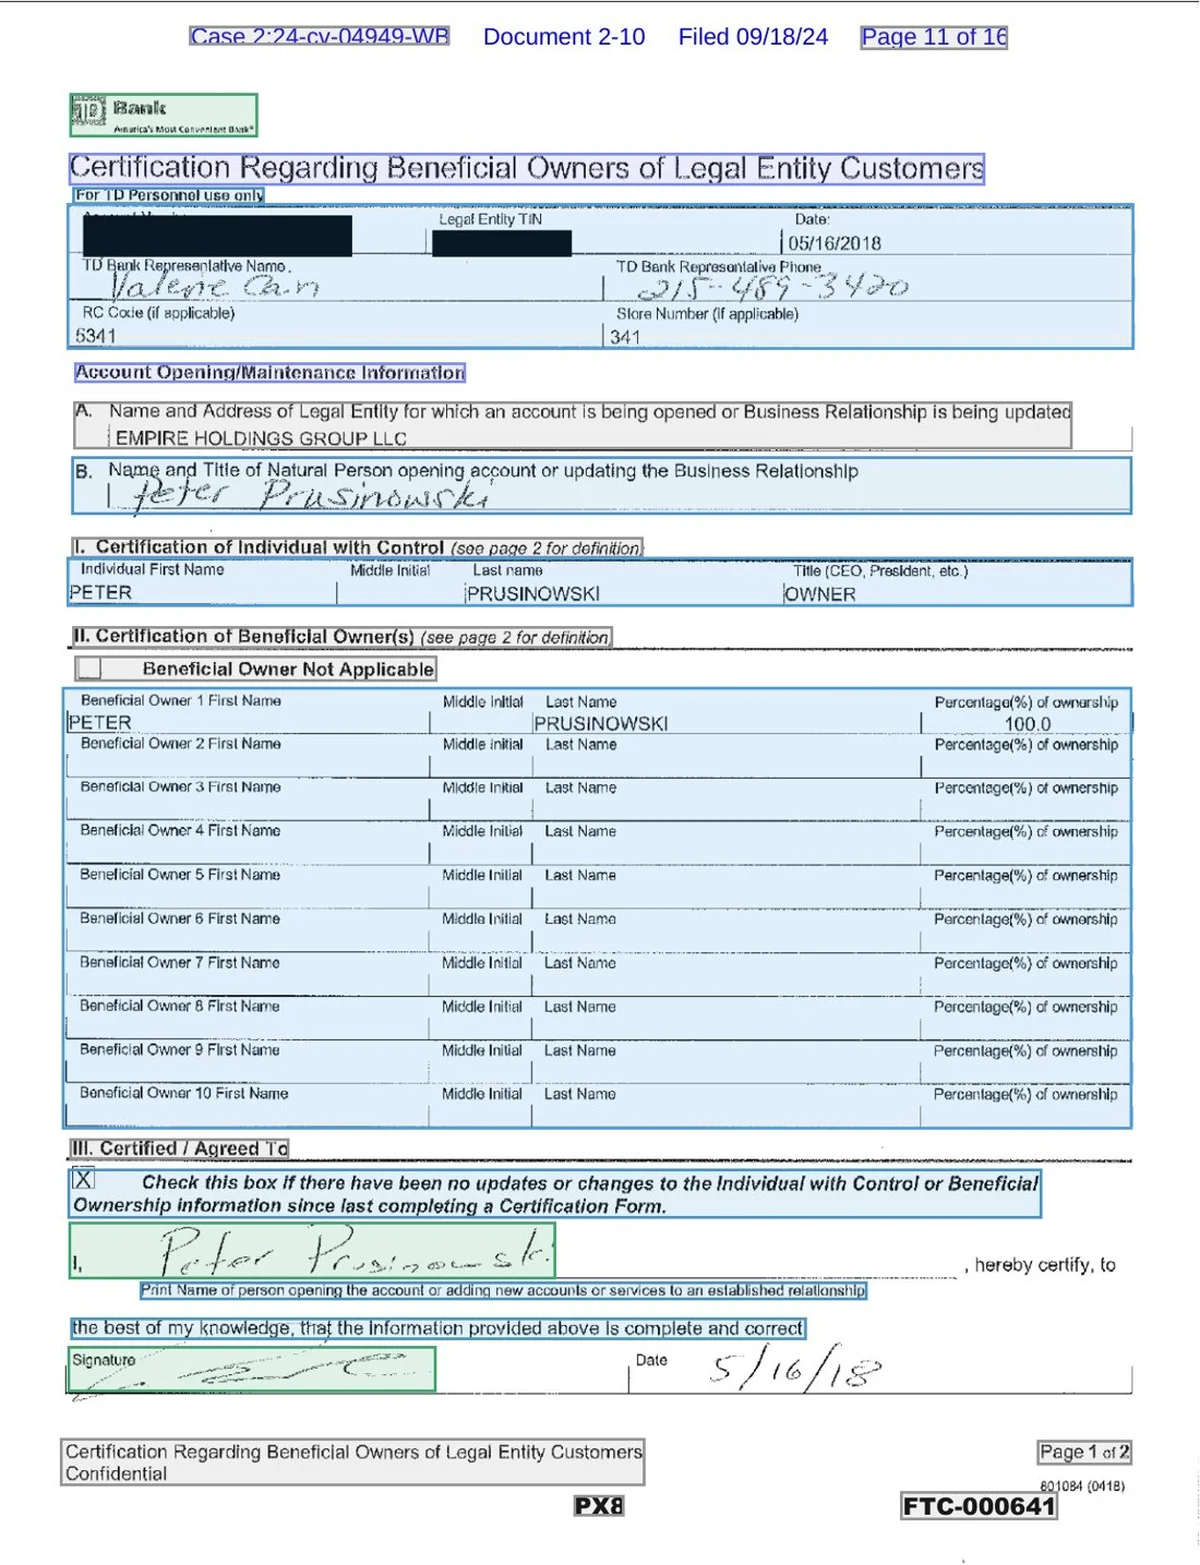 Ownership form, typed
Highlighted cells are where the documents disagree. Lens read each value as printed.
Account-opening form | IRS EIN notice | Articles of organization | Ownership form, handwritten | Ownership form, typed | |
|---|---|---|---|---|---|
Company | Empire Holdings Group LLC | Empire Holdings Group LLC | Empire Holdings Group LLC | Empire Holdings Group | Empire Holdings Group LLC |
Owner | Peter P Prusinowski | Peter Prusinowski | — | Peter P Prusinowski | Peter Prusinowski |
Date | 2018-05-16 | 2018-05-09 | 2018-04-19 | 2018-06-18 | 2018-05-16 |
Lens read each document into the same fields and flagged three differences. "LLC" is missing on one form. The owner's middle initial appears on only some. The two ownership forms are dated a month apart.
Measuring on public benchmarks
We picked the documents above because they represent what Pointer sees in production. We also wanted to know how well Lens generalizes beyond our own documents. So we ran it on two popular third-party benchmarks with public leaderboards.
Lens has two core jobs. Extraction pulls specific values out of a document, like an invoice number or a total, for a workflow to use. ExtractBench Pro scores it two ways. Value F1 is a score out of 100 that counts both wrong values and missed ones. The other score is the number of documents that are 100% right.
Parsing turns a page into text and structure, like tables, headings and charts, for an agent to read. ParseBench scores text, tables, charts, formatting and layout.
We used each benchmark's own scorer. We compared against the leaderboards as published (ParseBench on October 8, 2026 and ExtractBench Pro on October 15, 2026). LlamaIndex publishes both benchmarks and also builds LlamaExtract and LlamaParse, which appear on the leaderboards. The tables show the products built for each job. The ExtractBench Pro cost charts also show the coding agents and general-purpose models on the leaderboard, which are not extraction products.
Extraction
ExtractBench Pro has 100 synthetic documents, 2,622 pages in all, with known answers. They include values read off charts, relationships drawn as lines in a diagram, and sheets up to 200 inches long. Each document gets 30 minutes. A document that fails or runs over scores zero.
ExtractBench Pro ranks systems by how many documents they get 100% right, then by value F1. That is the measure that matters when no one checks the output. A document with one wrong value is a wrong document.
Lens got 58 of the 100 documents 100% right and a value F1 of 90.8. The next dedicated extraction system gets 38 documents right and a value F1 of 77.7, so Lens is 20 documents and 13.1 points ahead.
Here is how Lens gets there. A quick check on each page decides how the document is read. Documents with a lot of charts or diagrams go to a stronger agent that reads them on its own. Everything else is read twice, and one more model call settles any field where the two reads disagree.
The table shows the dedicated extraction systems on the leaderboard with Lens in rank order. The best score in each column is in bold.
ExtractBench Pro | Documents 100% right (of 100) | Value F1 | Cost per page |
|---|---|---|---|
Lens | 58 | 90.82 | 12.0¢ |
LlamaExtract Agentic Plus | 38 | 77.70 | 7.5¢ |
Extend Operator | 34 | 73.87 | 9.9¢ |
LlamaExtract Agentic | 20 | 71.32 | 3.1¢ |
Pulse Effort | 18 | 70.53 | 10.5¢ |
Reducto Deep Extract | 3 | 56.35 | 6.2¢ |
Datalab Accurate | 2 | 43.93 | 15.8¢ |
LlamaExtract Cost Effective | 0 | 47.19 | 1.0¢ |
Lens's cost is what we paid per page on OpenAI's flex tier. The other systems' costs are their published list prices.


By challenge category, Lens has the highest value F1 of the dedicated systems on five of the six: drawn relations (97.9), long chart sheets (83.4), house counting rules (71.5), charts inside documents (96.3) and house vocabulary (99.8).

Parsing
Lens scored 88.51 overall on ParseBench. That is second of 145 systems. The only system ahead of it is LlamaParse Agentic Plus (90.20), from LlamaIndex, which publishes the benchmark. It costs 5.6¢ a page, against Lens's 0.19¢. Lens is the highest-scoring system from any other provider, almost 7 points ahead of the next one.
The table shows the top 10 dedicated parsing products on the leaderboard with Lens in rank order.
ParseBench | Overall | Cost per page |
|---|---|---|
LlamaParse Agentic Plus | 90.20 | 5.6¢ |
Lens | 88.51 | 0.19¢ |
LlamaParse Agentic | 87.01 | 1.25¢ |
Pulse Ultra 2 | 81.60 | 1.5¢ |
LlamaParse Cost Effective | 80.61 | 0.38¢ |
anyformat (Standard) | 80.30 | 4.3¢ |
oi-parser | 78.30 | not published |
Nutrient DWS (Agentic) | 76.43 | 1.80¢ |
Extend (2.0) | 75.33 | 2.5¢ |
Databricks AI Parse | 74.71 | 0.35¢ |
Lens's cost is what we paid per page on OpenAI's flex tier. The other systems' costs are their published list prices.

How Lens works
Lens uses ordinary code wherever an answer can be exact. It uses a language model only where reading takes judgment. The pipeline has three stages.

1. Mapping the page before the model sees it
Lens first runs layout detection and OCR locally, without calling a model. Layout detection finds each table, heading, figure and text block on the page and labels it. These are the boxes in the figures above. On scans, OCR gives a first pass of the text, and later stages check it against what the model reads. When a PDF already has a text layer, Lens copies the exact characters instead of reading them again.
We do this in code because code is exact, free per page and repeatable. The same page gets the same map on every run. Where a table starts and ends never shifts between runs.
2. Reading each region with a model
For extraction, Lens picks a reading strategy for each document.
Short documents go to the model in a single pass.
Long tables are read in page windows, so a bank statement that runs dozens of pages is never squeezed into one call.
Scans and photos go in as images.
Everything else is split into chunks and stitched back together.
For parsing, Lens re-reads tables and charts from a close-up crop. Dense numbers and small labels are where a model is most likely to misread.
3. Verify the answer in code
Lens treats the model's output as a draft. Code counts the rows the model returned and compares that with the rows on the page. It adds up the line items and compares the sum with the printed total. Anything that doesn't match is read again.
What's next
Benchmarks test one document at a time, but real work comes as a thread of documents, where Pointer has to find the right one, carry a correction from one to the next and check the result. That is where most of our work on Lens goes now.
Pointer reads more documents every month. Lens is one example of how we build. Instead of stitching together third-party tools for a quick fix, we go deeper down the stack and build each primitive ourselves, shaped by the work our customers run on Pointer.
If you want to build systems like this, we're hiring.


